Does a keyword-spotting accelerator fit in a Tiny Tapeout tile, and how accurate can it be?
research/accel-ttfit
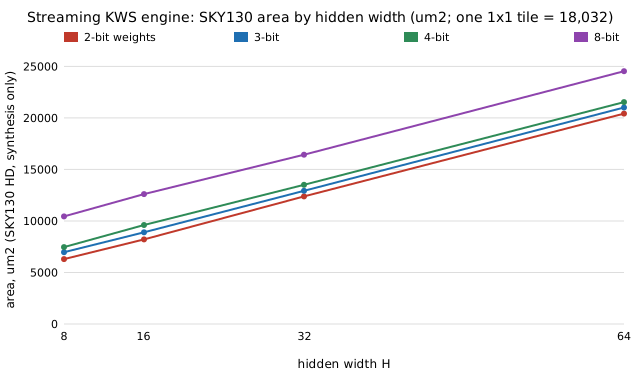
A streaming keyword-spotting engine with no weight memory, exact against an integer reference and synthesised to SKY130 on 32 geometries (6,300 to 24,500 um2); 16 hidden units at 8-bit weights is the most accurate (0.616) that fits one assumed 1x1 Tiny Tapeout tile at 70% utilisation, 64 units at 4 bits (0.738) needs two. Stylised: synthesis only.
What it found
A streaming serial-MAC engine with no weight memory (the host feeds one operand pair per clock over the 16 input pins; hidden activations sit in a rotating shift register), bit- and cycle-exact against an integer reference in Icarus on 32 geometries, synthesised to SKY130 HD with Yosys. Area is 6,300–24,500 µm2 (661–2,090 cells) for 8–64 hidden units and 2–8 bit weights; flops are 33–53% of it, and 8-bit weights cost about 3,000 µm2 more than 4-bit. Against an assumed 161×112 µm 1x1 tile (18,032 µm2), the best model by accel-kws test accuracy that fits one tile at 70% utilisation is 16 hidden units, 8-bit weights, 120 inputs (0.616); two tiles take 64 units at 4 bits (0.738), a 1.7× area step for 12 points. Stylised: synthesis only (no placement, routing or timing), random weights in the RTL check, accuracies carried over from accel-kws models that were not re-run through this engine, and the tile area is from a search-result snippet of a Tiny Tapeout guide, not the tile table.
A figure from its own output
Paper, code and results
More in Task-specific AI accelerators
- Under a latency deadline, how much engine area does picking the most accurate model first cost, compared with choosing model and lane count together?Model-first vs joint choice of model and MAC lane count under a latency deadline, on the 40 measured
accel-kwsmodels; accepting 2 validation points less cuts engine area 31–42% (stylised, table-based, cycles for more than one lane analytic). - Does NSGA-II find a keyword-spotting accelerator's Pareto front faster than random search at equal budgets?NSGA-II against random search at equal budgets on a 3,840-design keyword-spotting accelerator space with exact ground truth; NSGA-II finds 54 to 89% of the exact front at 20.8% of the space against 19 to 21% for random search, though hypervolume is 0.97 to 1.00 for both. Stylised.
- Was accel-nsga's NSGA-II win a tuning accident? Does population size, mutation rate or crossover change how much of the exact front it finds?Sweeps NSGA-II's population, mutation rate and crossover on the
accel-nsgaspace; mutation 0.02 to 0.1 finds about 0.38 and 0.71 to 0.77 of the exact front at 400 designs, against 0.28 and 0.59 ataccel-nsga's setting and 0.13 and 0.12 for random search (stylised). - Which dataflow should a small keyword-spotting accelerator use, and does the answer survive allowing an input buffer?Weight-, output-, input-stationary and reduction-tree dataflows of a P-lane MAC array on the 40
accel-kwsmodels, from a cycle-by-cycle schedule simulator that matches closed forms exactly and the P = 1 RTL cycles; output-stationary wins on SRAM energy at batch 4 until an input buffer is allowed, then input-mapped flows win at 32 lanes (stylised, assumed energy constants, no RTL for more than one lane). - How large must an activation buffer be before the best dataflow for a small keyword-spotting accelerator changes?How large a bounded LRU activation buffer must be before output-stationary stops being the best dataflow for the 40
accel-kwsmodels at batch 4: 32, 64 and 128 words at 8, 16 and 32 lanes (for 10 to 30 of 40 models, input-stationary wins), and not at all at batch 1; buffer-read energy is assumed and no area is charged (stylised). - Does a loop-nest cycle model of a P-lane MAC array match RTL at more than one lane, tails included?P-lane output-stationary and reduction-tree matrix-vector engines in Verilog, bit-exact against NumPy at 1 to 32 lanes, with RTL cycles equal to
accel-dataflow's schedule model plus a constant 2 or 3 at every point, tails included (stylised, generic-gate area, batch 1, no memories).
All 40 Task-specific AI accelerators projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.