Was accel-nsga's NSGA-II win a tuning accident? Does population size, mutation rate or crossover change how much of the exact front it finds?
research/accel-nsgatune
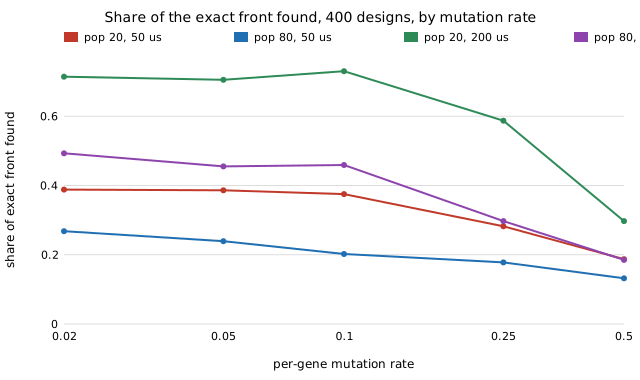
Sweeps NSGA-II's population, mutation rate and crossover on the accel-nsga space; mutation 0.02 to 0.1 finds about 0.38 and 0.71 to 0.77 of the exact front at 400 designs, against 0.28 and 0.59 at accel-nsga's setting and 0.13 and 0.12 for random search (stylised).
What it found
A sweep of NSGA-II population size (10–80), per-gene mutation rate (0.02–0.5) and crossover on the 3,840-design keyword-spotting accelerator space of accel-nsga, at 400 evaluated designs, 30 seeds, scored against the exact front. The earlier setting (population 20, mutation 0.25) was under-tuned: mutation 0.02–0.1 finds about 0.38 of the front at 50 µs (was 0.28) and 0.71–0.77 at 200 µs (was 0.59), against 0.13 and 0.12 for random search. Population 80 with mutation 0.5 is no better than random. Removing crossover changes little. Stylised: one budget, four genes, tuned on the score it is reported with.
A figure from its own output
Paper, code and results
More in Task-specific AI accelerators
- Which dataflow should a small keyword-spotting accelerator use, and does the answer survive allowing an input buffer?Weight-, output-, input-stationary and reduction-tree dataflows of a P-lane MAC array on the 40
accel-kwsmodels, from a cycle-by-cycle schedule simulator that matches closed forms exactly and the P = 1 RTL cycles; output-stationary wins on SRAM energy at batch 4 until an input buffer is allowed, then input-mapped flows win at 32 lanes (stylised, assumed energy constants, no RTL for more than one lane). - How large must an activation buffer be before the best dataflow for a small keyword-spotting accelerator changes?How large a bounded LRU activation buffer must be before output-stationary stops being the best dataflow for the 40
accel-kwsmodels at batch 4: 32, 64 and 128 words at 8, 16 and 32 lanes (for 10 to 30 of 40 models, input-stationary wins), and not at all at batch 1; buffer-read energy is assumed and no area is charged (stylised). - Does a loop-nest cycle model of a P-lane MAC array match RTL at more than one lane, tails included?P-lane output-stationary and reduction-tree matrix-vector engines in Verilog, bit-exact against NumPy at 1 to 32 lanes, with RTL cycles equal to
accel-dataflow's schedule model plus a constant 2 or 3 at every point, tails included (stylised, generic-gate area, batch 1, no memories). - Does the weight-stationary advantage in the dataflow model survive RTL at batch above 1, and what does it cost in gates?Output- and weight-stationary batched RTL engines at batch 1 to 16: bit-exact, cycles and operand-fetch counts equal
accel-dataflow's schedule model, and weight-stationary's saved weight fetches cost up to 4x the generic gates (stylised, P = 8, no memories). - How cheap must idle flops be, relative to a weight fetch, for register-file weight-stationary to beat output-stationary?Breakeven price ratios from accel-planebatch's RTL counts: register-file weight-stationary beats output-stationary only if an idle flop costs under ~1% of a weight fetch per cycle at batch 4 (falling ~1/B); no energy constant measured (stylised).
- At SKY130's own energy prices, does register-file weight-stationary scheduling beat output-stationary?Places accel-fetchprice's breakevens against SKY130 liberty energies (idle flop 46 fJ per cycle; OpenRAM macro 10 to 90 pJ per access): with weights packed into SRAM words register-file weight-stationary loses to output-stationary at nearly every batch; partial sums in SRAM lose everywhere. Library values, not measurements.
All 40 Task-specific AI accelerators projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.