When does a task's accuracy tolerance let an accelerator drop its multipliers?
research/accel-sparse
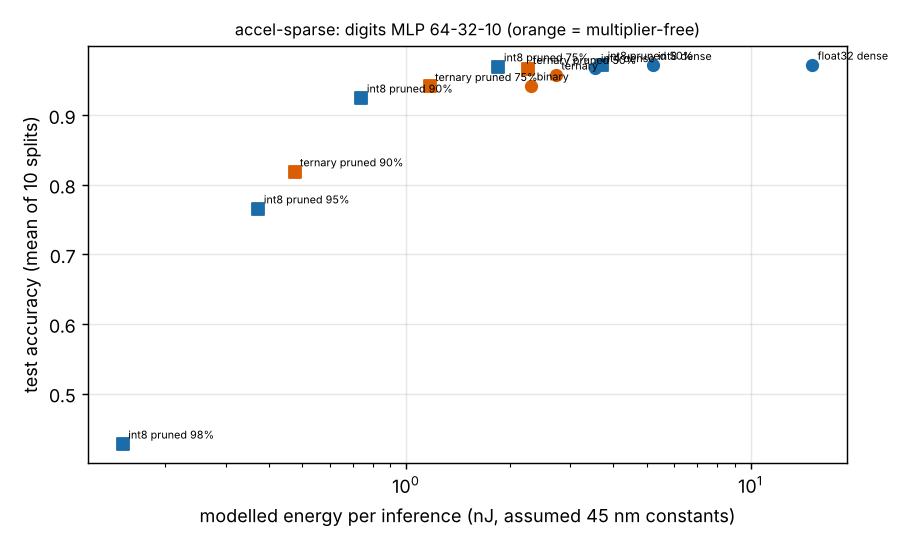
Pruning, int4/int8, ternary and binary MLPs on scikit-learn digits (substitute task) with a modelled-energy engine: when does the accuracy slack let the hardware drop multipliers? Stylised; at 1–2 points tolerance, pruned int8 still beats multiplier-free.
What it found
Pruning, int4/int8, ternary and binary variants of a 64-32-10 MLP on scikit-learn's 8×8 digits (a substitute task: Speech Commands was unreachable), with a modelled energy per inference for a zero-skipping serial engine, over 10 splits. Pruning 75% of int8 weights costs 0.2 points and cuts modelled energy to 36% of dense int8; ternary costs 1.4 points and binary 3.0. Within 1–2 points of float32 the cheapest design still has multipliers, because operand reads dominate in the assumed model; multiplier energy must be about 10× the assumed value before dropping it clearly pays. Stylised: assumed 45 nm constants, no RTL or synthesis, no lookup-table variant, toy task.
A figure from its own output
Paper, code and results
More in Task-specific AI accelerators
- Does the pruning and ternary-weight result from digits hold on real keyword-spotting features?
accel-sparse's pruning, int4/int8, ternary and binary sweep re-run on real Speech Commands MFCC features: no multiplier-free design is within 5 points of float32 (ternary 19 down), where digits said 1; int8 pruned 50% is the cheapest within 2 points. Stylised, untuned negative. - Does weight-sharing lookup-table inference beat a multiply-accumulate engine for a small accelerator?Weight-sharing product-table inference against int8 MAC engines on the digits MLP: negative at this size, break-even only for wide layers with cheap table reads. Stylised, modelled energy.
- Does a wider hidden layer make weight-sharing product-table inference beat an int8 MAC engine?Product-table inference on trained wide digits MLPs (32, 128, 512 hidden): at best 14% under int8 energy, only with an assumed cheap table read. Stylised, modelled energy.
- Does fine-tuning the shared weight values rescue low-K lookup-table inference?Fine-tuning the shared values of
accel-lut's product-table engine: rescues K=2 in the 75%-pruned digits MLP (14% under int8 energy only at an assumed cheap table read), not the dense network. Stylised, modelled energy. - What does a product-table inference engine cost in RTL, against a serial MAC engine?The product-table engine and a serial MAC engine in Verilog, bit-exact against NumPy and synthesised with Yosys: negative, the table needs an accumulator per output (stylised)
- Does a tiny always-on keyword model that wakes a bigger one beat the best single model on energy?Classifier-only energy of two-stage keyword-spotting cascades vs 40 single MLPs retrained on the original Speech Commands v0.02 (5 seeds, 200 models, about 41,000 cascades per seed, thresholds chosen on validation): cascades cut modelled energy by 0 to 28% at the same validation target, losing 0.3 to 1.4 test points, and the saving is under 1% of a system whose MFCC front end costs about 50 times the classifier
All 40 Task-specific AI accelerators projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.