Does fine-tuning the shared weight values rescue low-K lookup-table inference?
research/accel-lutft
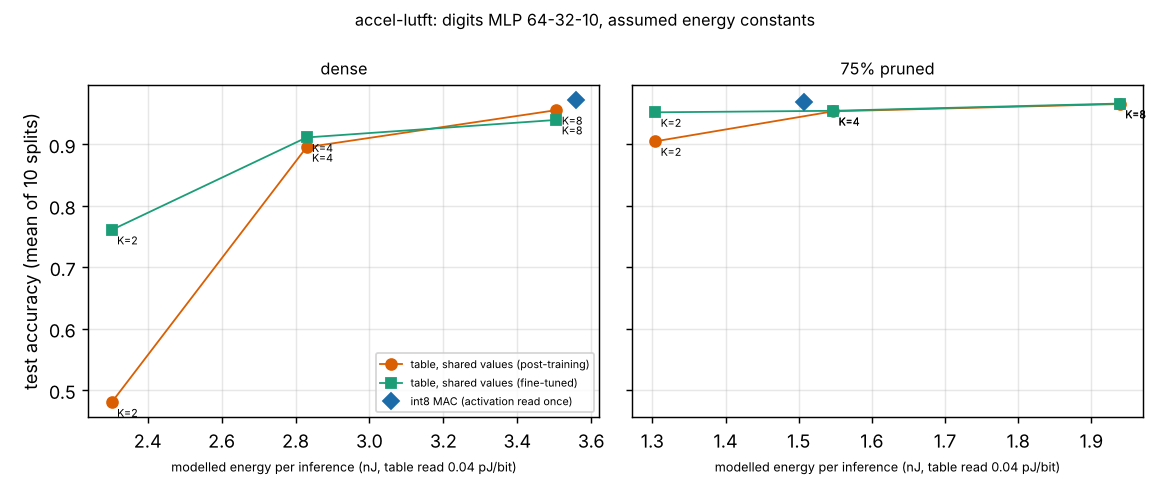
Fine-tuning the shared values of accel-lut's product-table engine: rescues K=2 in the 75%-pruned digits MLP (14% under int8 energy only at an assumed cheap table read), not the dense network. Stylised, modelled energy.
What it found
accel-lut left its shared values untrained. Here the codebook is kept in the loop for 60 epochs (straight-through, k-means re-fit each step) on the same 64-32-10 digits MLP, dense and 75% pruned, over 10 splits. Mixed: in the pruned network 2 shared values go from a 6.5-point to a 1.7-point accuracy drop, and with an assumed cheap table read (0.04 pJ/bit) that is 1.30 nJ against 1.51 nJ for int8; at 0.16 pJ/bit it loses. In the dense network fine-tuning does not help (8 shared values: 3.2 points down against 1.6 without it). Stylised: assumed energy constants, one fine-tuning recipe, no RTL, substitute task.
A figure from its own output
Paper, code and results
More in Task-specific AI accelerators
- What does a product-table inference engine cost in RTL, against a serial MAC engine?The product-table engine and a serial MAC engine in Verilog, bit-exact against NumPy and synthesised with Yosys: negative, the table needs an accumulator per output (stylised)
- Does a tiny always-on keyword model that wakes a bigger one beat the best single model on energy?Classifier-only energy of two-stage keyword-spotting cascades vs 40 single MLPs retrained on the original Speech Commands v0.02 (5 seeds, 200 models, about 41,000 cascades per seed, thresholds chosen on validation): cascades cut modelled energy by 0 to 28% at the same validation target, losing 0.3 to 1.4 test points, and the saving is under 1% of a system whose MFCC front end costs about 50 times the classifier
- Does the MFCC front end cost more than the keyword-spotting network it feeds?An instrumented Q15 MFCC front end (512-point FFT, 40 mel bands, DCT) costs 7,532 multiplies per 20 ms frame against the 5,184-MAC
accel-kwsclassifier per inference; under assumed 45 nm constants the front end is 8 to 150 times the classifier's power, and 16-bit FFT scaling decides its accuracy (synthetic frames, no Speech Commands) - Does block floating point fix the 16-bit FFT scaling problem in an always-on MFCC front end?A shared data-chosen exponent for the 16-bit FFT in
accel-frontend's MFCC path cuts cepstral error to 0.016 to 0.081 of the spread at -60 to -30 dBFS (one shift per stage: 0.35 to 0.72) for about +0.5% modelled energy, but no better than 18 to 20-bit fixed schedules on loud input (synthetic frames, no Speech Commands) - Do the accel-* energy constants match Horowitz (2014), and does fixing the array-size term change accel-kws's conclusions?All 34 energy constants in the accel-* projects that have a counterpart in Horowitz's Fig. 1.1.9 are within 4% of it; re-costing accel-kws with the figure's array-size law (energy about the square root of size) moves energy to 0.23 to 0.81 of as built but keeps 17 of 18 front designs (Spearman 0.991)
- Does weight-sharing lookup-table inference beat an int8 MAC engine once small arrays cost less to read?Pricing every array by its own size flips accel-lut's negative result once read energy grows faster than size^0.26 (dense) or size^0.28 (pruned); Horowitz's slope is 0.5 above 8 KB but there is no point below it, so the verdict is conditional
All 40 Task-specific AI accelerators projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.