When should a twin run that counts rare failures stop?
research/stop-twin
When to stop a twin run counting rare failures: sequential Wald stopping halts on zero failures (90% of runs at p=10⁻³, coverage 9.6%), inverse sampling to m failures gives exactly unbiased (m−1)/(N−1) with relative sd ≈1/√(m−2) and an exact interval (95.0–95.5%), while a fixed run planned for the wrong p delivers 63–200% half-width.
What it found
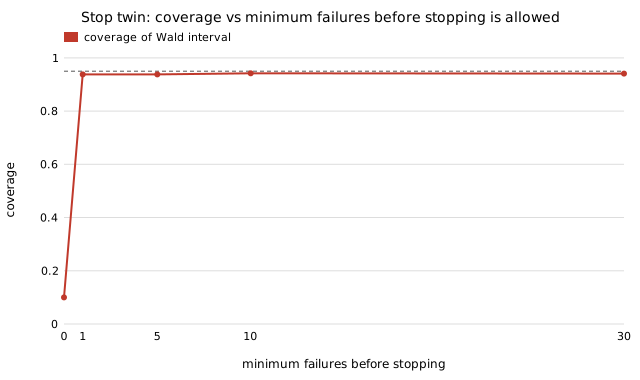
Running a safety twin “until the interval is narrow” stops on zero failures, because p̂=0 has Wald half-width 0: with a target of p/5, 90% of runs stop at the first check for p=10−3 (99% at 10−4), the interval covers p in 9.6% of runs and the reported rate is 10× too low. Running until m failures (inverse sampling) makes (m−1)/(N−1) exactly unbiased while m/N is about m/(m−1) too high, gives relative sd ≈1/√(m−2) whatever p is (m=102 for 10%; measured 0.101), and an exact interval covers 95.0–95.5%. A fixed run planned for p=10−3 delivers a 20% relative half-width there but 63% at 10−4. A one-failure minimum alone restores Wald coverage in this configuration, because the target already forces ~96 failures. Stylised (iid Bernoulli failures, faithful twin, no run cap).
A figure from its own output
Paper, code and results
More in Digital twins & sim-to-real
- What stopping distance can a twin with independent terrain cells certify?Stopping distance certified by a twin with independent per-cell friction: exact incomplete-gamma law (matches braking simulation), 100 twin cells certify 1.17× the mean distance but real terrain with 1–10 patches exceeds it 44%–18% (claimed 0.1%), finer cells are worse, the mean is nearly right, and the measured patch count repairs it.
- What approach speed can a lidar twin that returns every beam certify?Approach speed certified by a lidar twin with independent beam dropout vs real whole-scan fades: exact scan-product miss law, real miss ~100× the level at the twin's speed, speed off 10–30% (probabilities off by orders of magnitude), sign reverses when several returns are needed, repaired by a few hundred calibration scans.
- How do you estimate a one-in-a-million failure from a twin you can only run a thousand times?Importance sampling of a rare twin failure: exact mean-shift variance, 10⁸→535 runs for 10% error at p=1e-6, a narrow shift target (2× the optimum is 1.7·10⁵× worse, 0% coverage) and effective sample size as the only warning.
- Which ego-velocity estimator should a radar twin choose when the real scene has moving targets?Radar ego-velocity from Doppler returns: a static-world twin picks least squares, but with moving targets its variance is exactly
1+ετ²times the claim (95% interval covers 48.7% at ε=0.1, τ=10) and the median wins on a band of ε (0.006–0.97 at τ=10; never at τ=1). - A radar twin with no Doppler folding certifies an ego-velocity estimator at every speed: what does the folding sensor do to it, and when can it be unfolded?A radar twin with no Doppler folding: the twin-tuned ego-speed estimator breaks at
v_u−2σwith an exact closed-form bias (saturating at one fold off), and a wrapped-cost search unfolds it iff azimuths are diverse, with a confusion probabilityΦ(−√E₁/2σ)matching Monte Carlo. - How many real trials before “the twin passed validation” means anything for a rare failure?Validating a twin's rare-failure rate against real trials: an exact difference test "passes" a 3×-wrong twin 81% of the time at 500 trials, rejecting a 2× error needs ~11 real failures (any q), and an equivalence test needs ~20/58/178 failures for margins 2/1.5/1.25 (~20/q trials).
All 164 Digital twins & sim-to-real projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.