How do you pay a verifier whose report decides the job?
research/decision-scoring
Scoring verifiers whose report decides acceptance and whose outcome is seen only on acceptance: a truthful reserve exists iff the score centre τ_s ≥ τ_d (unique c0 = 1+τ_d²−2τ_dτ_s), plain Brier fails above τ_d = ½, recentring fixes it at rent τ³/3, exploration costs 1/ε payment variance.
What it found
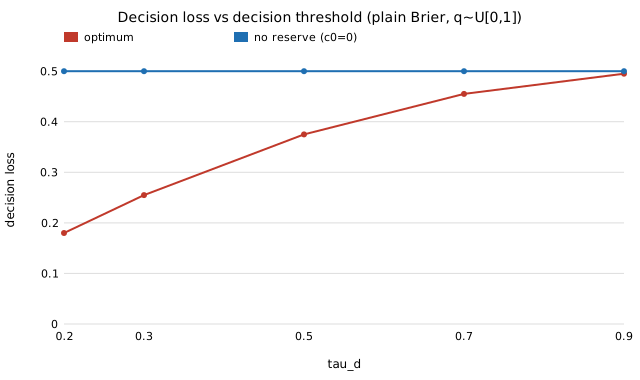
If a report of “fault” gets the job rejected and the outcome is seen only on acceptance, scoring observed jobs is improper: verifiers shade under the threshold to get scored, and every job is accepted (1.1–2.8× optimal decision loss at thresholds 0.7–0.2). A reserve payment for rejection makes truth optimal iff the score’s entropy minimum τs is at least the threshold τd, and then it is unique, 1+τd²−2τdτs. Plain Brier (τs=½) therefore fails above τd=½; recentring the score by a term linear in the outcome fixes every threshold, cheapest at τs=τd with rent τ3/3. Exploration with inverse-propensity payment is also proper but multiplies payment variance by about 1/ε. Stylised, single verifier.
A figure from its own output
Paper, code and results
More in Proper scoring & elicitation
- What if the referee itself is noisy?Scoring verifiers against a noisy judge: raw proper scores elicit
e0+γpand shrink Brier incentives byγ², can reverse rankings (η*=0.25), the unbiased surrogate score is exactly proper at a1/γpayment spread and1/γ²sample cost, and misestimated rates give a closed-form bias. - Can audits be predictable without corrupting scores?Scoring when truth exists only on audited tasks: report-dependent audit rates make naive scoring improper (shift
−bp(1−p)/(2(a+bp)), full hiding for steep rates), inverse-propensity weighting is exactly proper for any audit rule, and Neyman allocation gains only 3–11% variance. - Can a calibration test certify a verifier?Calibration tests are gameable: an information-free Foster–Vohra/Blackwell hedger keeps expected ECE ≤
√(K+1)(1/(2K)+1/√T)against any outcome sequence (measured 0.016, Brier 0.254 vs 0 informed), so slashing must use a resolution-sensitive score; a Brier-gap test detects it in 100/100 runs. - Can a protocol pay workers to report how often honest replicas agree?Eliciting the chance two honest runs of a nondeterministic op agree (Γ=Σp²) from run pairs: proper with exact regret, one run provably cannot, all-pairs U-statistic variance ~¼ of disjoint pairs, fleet of H hardware classes false-slashes strict equality at
1−H^{1−k}, colluders' blind spot at ε=2Γ/(1+Γ). - Is a skill score normalised by the realised base rate safe to pay on?Brier skill scores normalised by the realised base rate are improper: exact optimal report,
≈ −(1−2p)/nbias, cross-task leakage through the pooled baseline, and a leave-one-out fix. - Can interpretable models predict annual divorce incidence?Original U.S. marriage microdata: interpretable annual-divorce models, schooling/earnings pairings and reproducible held-out validation; no validated personal optimum.
All 28 Proper scoring & elicitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.