Can a protocol pay workers to report how often honest replicas agree?
research/collision-elicitation
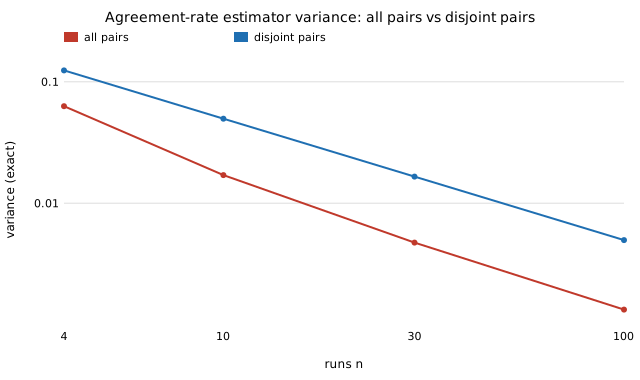
Eliciting the chance two honest runs of a nondeterministic op agree (Γ=Σp²) from run pairs: proper with exact regret, one run provably cannot, all-pairs U-statistic variance ~¼ of disjoint pairs, fleet of H hardware classes false-slashes strict equality at 1−H^{1−k}, colluders' blind spot at ε=2Γ/(1+Γ).
What it found
Yes, from two runs and no more: the squared error against the agreement indicator is proper for the collision probability Γ=Σpi2 with exact regret (r−Γ)2, and one run provably cannot (the level sets are not convex). The all-pairs U-statistic has exact variance and needs about a quarter of the runs of disjoint pairs (variance ratio 0.27 at n=100). A fleet of H equal hardware classes has Γ=1/H, so strict equality over k honest replicas false-slashes with probability 1−H1−k. Colluders returning one common wrong value leave agreement unchanged at ε=2Γ/(1+Γ), so Γ cannot be used alone. Runs are i.i.d. and float32 fleets are simulated summation orders.
A figure from its own output
Paper, code and results
More in Proper scoring & elicitation
- Is a skill score normalised by the realised base rate safe to pay on?Brier skill scores normalised by the realised base rate are improper: exact optimal report,
≈ −(1−2p)/nbias, cross-task leakage through the pooled baseline, and a leave-one-out fix. - Can interpretable models predict annual divorce incidence?Original U.S. marriage microdata: interpretable annual-divorce models, schooling/earnings pairings and reproducible held-out validation; no validated personal optimum.
- Property elicitation for verifiable ML trainingProperty elicitation (quantile/expectile/Bregman scores, non-elicitability of variance) applied to pricing tail-drift tolerance thresholds in verifiable ML training.
- How many bits does a probability report need?Finite-precision probability reports under proper scoring: optimal-grid regret law matched to 0.3%, uniform grids lose a
ln Nfactor under log score, raw minifloat formats are ~13× worse than symmetrised. - What do risk-averse verifiers report under proper scoring?Risk-averse verifiers under proper scoring: log score reports exactly
odds^(1/(1+αb)), Brier reports solvelogit p = logit r + k(2r−1)and can be debiased exactly, a mean-kaggregation correction is worse than none, and a binarised lottery rule is truthful for any utility at a 2.6–27% certainty-equivalent cost. - What does a verifier's silence tell you?Selective reporting under proper scoring: abstention iff
|p−α| < √c(Brier), silence is evidence unless the anchor is a symmetric prior, ignoring it costs 30× the log-loss at n=12, and a stale anchor makes silence point at the wrong state.
All 28 Proper scoring & elicitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.