Does a doubly robust estimator fix learning from an assistant’s own self-selected feedback?
research/ambient-dr
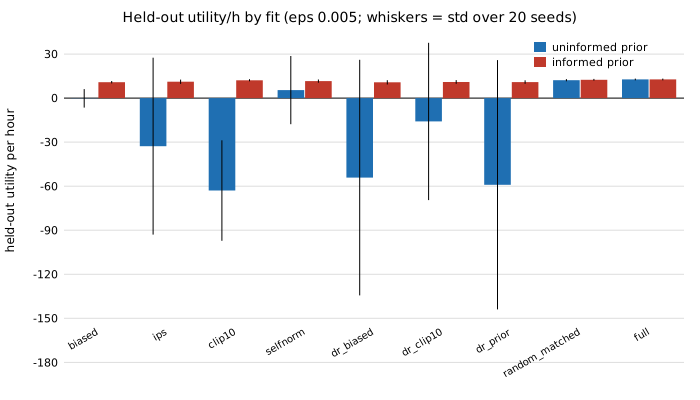
Does a doubly robust estimator beat IPS on an assistant's self-selected feedback: no, a stylised negative result; its pseudo-labels carry 1/ε residuals and are worse than the biased fit except with an informed prior.
What it found
A stylised follow-up to ambient-labelmatch. Doubly robust pseudo-labels (an outcome model plus an inverse-propensity correction on the windows where the assistant spoke) are fitted on every window and compared with biased, IPS, clipped and self-normalised fits on the same logged history. A negative result: with an uninformed prior all three variants are far worse than the biased fit (utility per hour below −15 against 12.71 for the oracle) and have huge variance, and with an informed prior they are level with or above the biased fit at they match the biased fit at ε = 0.005 and 0.02 butepsilon; = 0.005 and 0.02 but are not better than clipped IPS. Simulated windows chosen by me; nothing is claimed about real users.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- Does capping the inverse-propensity correction rescue doubly robust learning from an assistant’s own feedback?Does capping the inverse-propensity correction rescue doubly robust learning from an assistant's own feedback: with an informed prior yes (the collapse at ε = 0.002 goes from 0.26 to about 12 utility/h), with an uninformed prior no; stylised, simulated only.
- Does cross-fitting the outcome model help capped doubly robust learning from an assistant’s own feedback?Does fitting the doubly robust outcome model out-of-sample (2-fold cross-fitting) help the capped correction: no, a negative result; differences are within seed noise or worse, and the unclipped collapse at ε = 0.002 persists (1.53 vs 0.26 utility/h); stylised, simulated only.
- Can the doubly robust cap be chosen by validation on an assistant’s own logs?Can the capped doubly robust cap be chosen by 4-fold IPS validation on the log: with an informed prior it matches the best fixed cap within seed noise, with an uninformed prior it does not rescue learning; stylised, simulated only.
- Does a doubly robust validation score choose the doubly robust cap better than an IPS score?A doubly robust validation score does not pick the DR cap better than IPS with the same 4 folds (equal with an informed prior, mixed with the uninformed one); 8 random folds with the DR score is best in all three uninformed cells but still far below the label-matched control (stylised).
- Which of score, fold count and fold type made cap selection better in ambient-drvalid?Ablating the three changes in
ambient-drvalid(score, fold count, fold type): in the uninformed cells random folds help more than the DR score (IPS on 8 random folds is as good as DR on 8), no factor wins everywhere, and every selector stays far below the label-matched control (stylised, negative). - Do repeated random fold assignments stabilise validation-based cap selection?Repeated random fold assignments for cap selection in the ambient-assistant world (follow-up to
ambient-drablate): averaging 5 assignments helps the IPS-score selector at ε = 0.02 (3.5 → 5.3 utility/h) and nothing else beyond noise; stylised, simulated only.
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.