Can the log score be made payable?
research/tangent-log
Bounded-payment log score by quadratic tangent extension: strictly proper, log-identical on [ε,1−ε], worst-case payment exactly ln((1−ε)/ε)+1/(1−ε), 63× Brier's curvature per range at p=10⁻³, crossover p(1−p)=1/(2R), best cutoff ε=p.
What it found
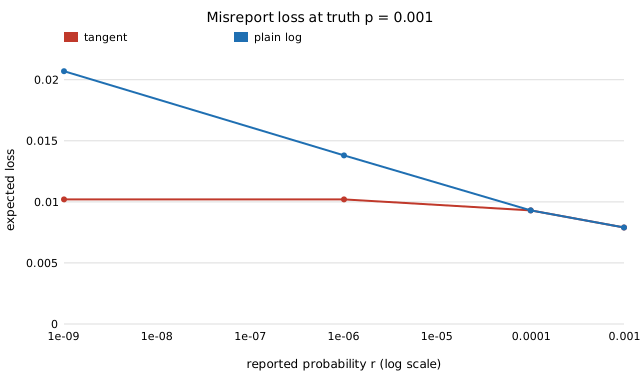
Log score is ideal for rare faults but a confident wrong report costs unbounded stake. Extending the log generator past [ε,1−ε] by its second-order Taylor polynomial gives a strictly proper score, identical to log up to a constant inside, with worst-case payment exactly ln((1−ε)/ε)+1/(1−ε). Per unit of payment range it has 63× Brier’s curvature at p=10−3 but loses to Brier above a closed-form crossover (≈0.07), and ε=p is the best cutoff for truth p.
A figure from its own output
Paper, code and results
More in Proper scoring & elicitation
- Which proper score should verifiers face with K outcomes?K-ary proper scores: exact worst-case regrets (
1−2p_min+‖p‖²Brier,‖p‖−p_minspherical), spherical beats Brier by exactly√Kper payment range at a uniform truth, and both bounded scores nearly ignore a dropped rare class (1e-4 vs 0.15 for log). - Can the multiclass log score be made payable?Bounded multiclass log score by quadratic tangent extension of
x ln x: log-identical when allr_j≥ε, payment range exactly1−ln εfor any K, 63× Brier's rare-class incentive per range at ρ=10⁻³ with best cutoff ε=p_min, and a closed-form bounded cost for dropping a rare class. - What does it cost to pay for a ranking instead of probabilities?Eliciting class rankings with linear rank-weight scores: strictly proper, adjacent-swap regret exactly
(p_i−p_j)(w_r−w_{r+1}), beats Brier-derived rankings per unit range below gap1/(K−1)(250× at gap 10⁻³), equal spacing is optimal, top-k set costs the same as the mode, detection sample size unchanged. - Should severity reports be scored with the order in mind?Ranked probability score for ordered severities: exact regret
Σ(R_k−P_k)², shift over distance d costsdε²(Brier2ε²), pooling adjacent classes costs half of Brier's, threshold errors ≤√regret, and per range RPS never beats Brier's incentive. - Can the tail of benign drift be elicited with a proper score?Jointly eliciting VaR and expected shortfall of benign drift: 0-homogeneous Fissler–Ziegel score minimised at (VaR, ES) with profile
ln ES, ES alone non-elicitable (mixture 12.5 vs 10), exact regret formulas, ES-understatement of 30% detectable with ~1k samples at τ=0.95 while pinball is blind. - Can we elicit the mode of a mixture of honest and cheating drift?Eliciting the modal drift with the window loss
1[|y−r|>α]: exact window-mass regret, best widthα=σ(normal) /γ/√3(Cauchy), closed-form critical widthα*above which bimodal drift has one α-mode, and 0 bias against contamination where the mean moves5ε.
All 28 Proper scoring & elicitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.