How few rollouts can a capped certification test need while keeping both errors at 5%, and how far is the tuned SPRT from that optimum?
research/free-sprtopt
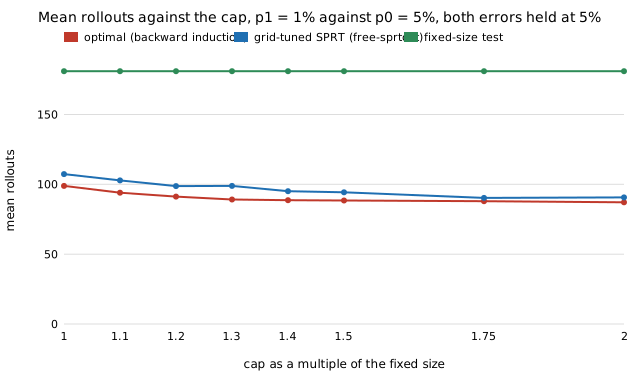
Follow-up to free-sprtcut: backward induction gives the optimal capped test, 98.9 rollouts on average for 1% vs 5% at a cap of 181 (proved within 0.2% by a dual bound), against 107.3 for the grid-tuned SPRT and 181 for the fixed test; the tuned SPRT is 3 to 9% above the optimum at every cap tried.
What it found
free-sprtcut re-tuned a capped SPRT on a coarse grid and listed “a backward-induction optimal truncated design” as the way to see how much was left. This project computes it. For multipliers c0, c1 the Bayes test minimising Ep0[N] + Ep1[N] + c0Pp0(accept) + c1Pp1(reject) is found exactly by backward induction over (rollouts, failures). Any test holding both errors at 5% costs at least that value minus 0.05(c0 + c1), a lower bound valid for every test including randomised ones; the best deterministic Bayes rule that holds both errors is the upper bound. For p1 = 1% against p0 = 5% (fixed test 181 rollouts) the optimal mean is 98.8–98.9 at a cap of 181, 94 at 1.1×, 88 at 1.5× and 87 at 2× and beyond; the bounds are within 1.1% of each other in all 21 cases (three (p0, p1) pairs, caps 1–3× the fixed size). The grid-tuned SPRT of free-sprtcut is 3–9% above the optimum in every comparable case (107.3 against 98.9 at 1×), and the optimum is roughly half the fixed test for 5% vs 1% and 10% vs 5%. Rollouts are assumed iid Bernoulli with the twin’s failure rate (no sim-to-real gap), the objective is the average of the two means only, the multiplier search is a local pattern search (the bounds, not the search, are what is certified), and nothing is sampled: every number is exact.
A figure from its own output
Paper, code and results
More in Digital twins & sim-to-real
- Is the overflow twin's lead over black-box models on a real two-tank rig statistically real? A 0.13 V RMSE gap over ARX 4/4 with a block-bootstrap 95% interval of 0.06 to 0.20 VIs the overflow twin's lead over black-box models on a real two-tank rig statistically real? A 0.13 V RMSE gap over ARX 4/4 with a block-bootstrap 95% interval of 0.06 to 0.20 V; the iid bootstrap is about three times too narrow. Test-trace sampling only, not fit variance.
- Does the overflow twin's lead over ARX survive refitting on a real two-tank rig? A 0.13 V gap in 100% of refits with 87.5% of the training data, but 0.07 V and 84 to 90% of refits with 50 to 75%Does the overflow twin's lead over ARX survive refitting on a real two-tank rig? A 0.13 V gap in 100% of refits with 87.5% of the training data, but 0.07 V and 84 to 90% of refits with 50 to 75%. Overlapping windows, fixed optimiser start.
- Does a physics digital twin beat black-box models on a real two-tank rig? 0.53 V test RMSE with 8 parameters vs 0.66 V for the best black boxDoes a physics digital twin beat black-box models on a real two-tank rig? An 8-parameter overflow twin gets 0.53 V test RMSE against 0.66 V for the best black box (9-parameter ARX); quadratic NARX models diverge in free run. One rig, one split, no confidence interval.
- Can a 22-DOF home robot be printed in PLA around one $15 servo, and which of its twin's simplifications matter for learning to reach and pick?A 3D-printable 22-DOF bimanual mobile manipulator (two 7-DOF arms with geared elbows and parallel grippers, head, lift, omni base) on one $15 servo, $627–948 in parts, with a MuJoCo twin generated from the same parameters as the CAD: reach and pick policies trained on the exact twin ignore servo, friction and mass errors but fail at one 40 ms step of latency (reach 99→29%, pick 91→41%); randomisation fixes reaching almost for free but costs picking 14 points; an interference sweep over the printed solids caught an elbow range the twin allowed but the parts could not reach. Simulated only, not yet built.
- How few real trials certify a robot policy when a biased simulator supplies the rest?Research programme (milestones 3 to 6 logged): valid, bias-agnostic sim-to-real evaluation of robot policies, consolidating about 130 twin projects into one question, with 13 checked references, hypotheses H1 to H6 and CoRL as the target venue
- A stereo twin that adds Gaussian noise to depth gets the median right: what does it get wrong about over-range errors, safety margins and averaging compared with real disparity-space noise?Gaussian-depth-noise stereo twin vs real disparity-space noise: median exact, gated mean biased by ≈s², over-range errors up to 191× more frequent at 40 m, a twin 3σ margin exceeded 10× as often, mean-depth averaging floors while averaging disparity converges (negative result at the 60 m range floor). Stylised.
All 164 Digital twins & sim-to-real projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.