Do cheap rungs of the chip-design tool ladder rank designs like synthesis, and how much synthesis time does screening save?
research/eda-fidelity
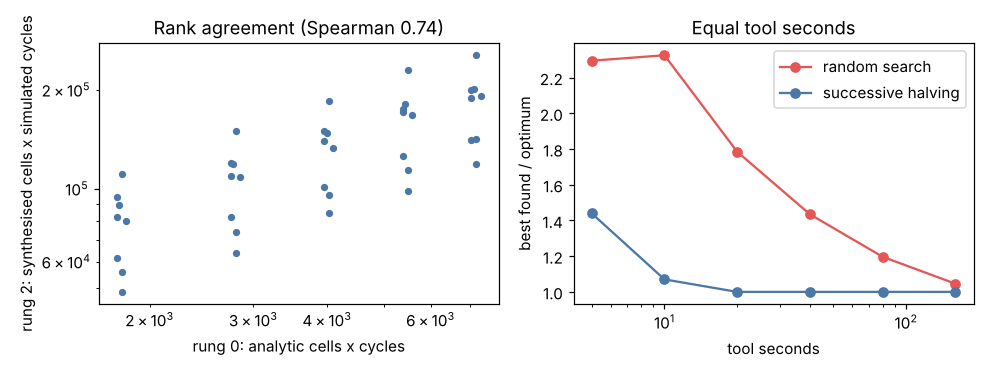
A three-rung fidelity ladder (analytic model, RTL simulation, synthesis) over 40 logged designs: the free rung ranks the objective at Spearman 0.74, and successive halving finds the optimum at 20 s of tool time against 205 s to synthesise everything (stylised, toy design family, no place and route).
What it found
A three-rung ladder over 40 logged MAC-engine designs: a free analytic model (cells ≈ lanes×bits2), cycle-accurate simulation, and Yosys synthesis. The analytic rung ranks the cells×cycles objective with Spearman 0.74 against synthesis (0.95 for cells alone) and finds 2 of the 5 best designs. Successive halving that screens on the cheap rungs reaches the optimum with certainty at 20 s of tool time, against 0.10 for random search at the same budget and 205 s for synthesising everything. Stylised: one toy design family with its optimum at a corner, no place-and-route rung, and the search is a replay over the committed log.
A figure from its own output
Paper, code and results
More in Algorithmic chip-design loops
- Can cheap word-level RTL features predict synthesised cell counts well enough to screen a design search, and does that survive a new design family?A cell-count surrogate from cheap word-level RTL features over 133 designs in four generator families: 3.9% median error on families it saw (non-negative linear model), 11% to 210% on a held-out family with rank agreement staying at Spearman 0.75 to 1.00, and it cuts syntheses to find a near-best design in a 36-design pool from 12.4 to 1-5 (stylised, synthesis-only target, no place and route).
- How many synthesised designs from a new family does a cell-count surrogate need before it is usable, and is it better to pool them with old families or train on them alone?Few-shot adaptation of the
eda-surrogatecell-count model to an unseen design family: one synthesised design from the new family cuts the linear model's median error from 49% to 18%, training on the new family alone beats pooling from about three designs, boosted trees need about 12 (stylised, synthesis-only target, no place and route). - Which few designs of a new family should you synthesise to adapt a cell-count surrogate, and should they count for more?Which few designs of a new family to synthesise when adapting a cell-count surrogate: a farthest-point spread in feature space roughly halves the linear model's error against random draws at 5 designs (5.3% against 8.5%), the smallest designs are worst, and upweighting new points helps linear and ridge but not boosted trees (stylised, synthesis-only target).
- Does the farthest-point spread still beat random draws when every chooser is scored on the same held-out designs?
eda-adaptpick's adaptation-design choosers re-scored on one fixed test set per family (4 families x 5 splits): the farthest-point spread still beats random draws for the linear model at every k (4.8% against 6.0% at 5 designs, w = 5) but wins in only 65% of cells, the smallest-first rule stays worst, and the earlier 'halves the error' margin shrinks to 20-45% at 5 to 8 designs. - Does a cell-count surrogate used as a screen find a chip design’s Pareto front with fewer syntheses than random search or TPE?A cell-count surrogate used as a screen in the design-search loop: 4 spread syntheses plus a log-linear fit reach 0.990 of the true front's hypervolume at 12 syntheses against 0.860 for random and 0.878 for TPE, of which about +0.05 comes from free cycles/error objectives (stylised, one 80-design space).
- How much error in a cheap objective can design-search proposers tolerate before they stop beating random search?With Gaussian error on the objectives a proposer sees, TPE's budget-30 lead over random falls from +0.037 to +0.006 (gone at error 0.8 of the objective range), NSGA-II and the genetic method lose theirs by 0.1, annealing is never better (stylised, synthetic noise, one 80-design space).
All 42 Algorithmic chip-design loops projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.