Should a verifier's continuous drift report be scored by CRPS or log score?
research/crps-drift-scoring
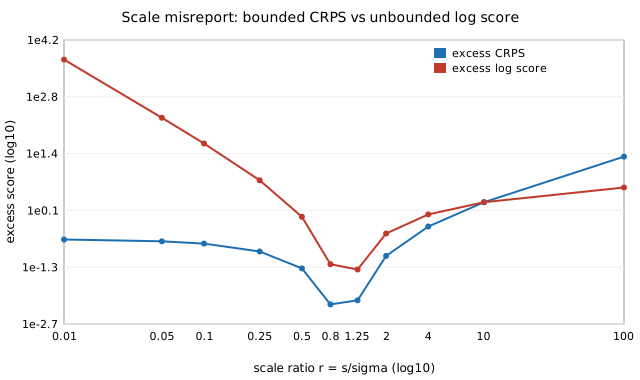
CRPS vs log score for continuous drift reports: exact Gaussian closed forms, overconfidence capped at 0.234σ under CRPS (unbounded under log), 1-Lipschitz outcome sensitivity, plug-in cost 5σ/(8√π n), and finite score variance for tails ν>2 vs ν>4.
What it found
For Gaussian reports N(m,s²) both rules have exact expected scores. Overconfidence costs at most σ(√2−1)/√π = 0.234σ under CRPS but is unbounded under log (4995 nats at s=0.01σ); mean errors cost linearly versus quadratically; CRPS is 1-Lipschitz in the realised outcome (log slope 75/σ in our example); a plug-in fit from n samples costs 5σ/(8√πn) versus 1/n; and per-round score variance is finite for Student-t tails ν>2 (CRPS) versus ν>4 (log), which matters for sequential tests. Gaussian family, one verifier. Stylised.
A figure from its own output
Paper, code and results
More in Proper scoring & elicitation
- Can a verifier be paid for reporting drift variance?Eliciting drift variance from two independent re-executions:
D=(y1−y2)²/2unbiased withVar=σ⁴(κ+1)/2, exact Brier and scale-free misreport costs (1/λ+ln λ−1), detection needs≈2z²(κ+1)/(λ−1)²tasks, disjoint pairs 1.8× worse than the sample variance, heavy tails breakm^{−1/2}concentration. - What can be elicited from several independent draws of benign drift?Eliciting drift *variance* from pairs of independent draws: exact pair score (excess loss
(r−σ²)²), degree table (mean² 2, third moment 3, σ⁴ 4), audit cost((z_α+z_β)/ρ)²(κ+1)/2pairs, robust Gini score beats it for heavy tails, all-pairs pooling saves(κ+1)/(κ−1), correlated draws bias the target toσ²(1−ρ). - Can the log score be made payable?Bounded-payment log score by quadratic tangent extension: strictly proper, log-identical on
[ε,1−ε], worst-case payment exactlyln((1−ε)/ε)+1/(1−ε), 63× Brier's curvature per range atp=10⁻³, crossoverp(1−p)=1/(2R), best cutoffε=p. - Which proper score should verifiers face with K outcomes?K-ary proper scores: exact worst-case regrets (
1−2p_min+‖p‖²Brier,‖p‖−p_minspherical), spherical beats Brier by exactly√Kper payment range at a uniform truth, and both bounded scores nearly ignore a dropped rare class (1e-4 vs 0.15 for log). - Can the multiclass log score be made payable?Bounded multiclass log score by quadratic tangent extension of
x ln x: log-identical when allr_j≥ε, payment range exactly1−ln εfor any K, 63× Brier's rare-class incentive per range at ρ=10⁻³ with best cutoff ε=p_min, and a closed-form bounded cost for dropping a rare class. - What does it cost to pay for a ranking instead of probabilities?Eliciting class rankings with linear rank-weight scores: strictly proper, adjacent-swap regret exactly
(p_i−p_j)(w_r−w_{r+1}), beats Brier-derived rankings per unit range below gap1/(K−1)(250× at gap 10⁻³), equal spacing is optimal, top-k set costs the same as the mode, detection sample size unchanged.
All 28 Proper scoring & elicitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.