Does a neural residual on top of the tuned PID get a quadrotor roll controller below the PID error floor?
research/codesign-aero-skip
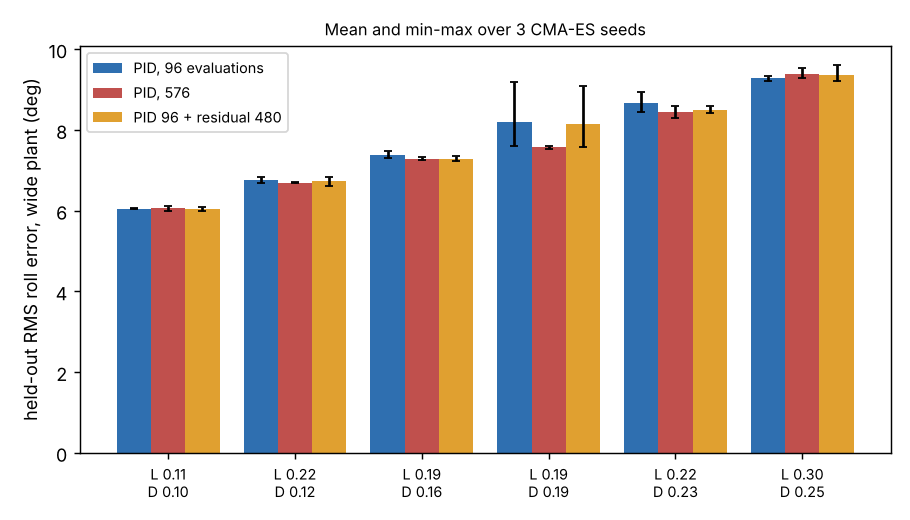
Does a zero-initialised neural residual on the tuned PID beat the PID on a randomised quadrotor? No at equal evaluations (7.68° against 7.58°, better in 7 of 18 pairs); the airframe ranking is unchanged (Spearman 1.00).
What it found
Follow-up to codesign-aero-mlp: the controller is the tuned PID plus a 31-parameter residual network that is exactly zero at the start, so CMA-ES begins at the PID. On six airframes spanning the wide-plant ranking, three seeds each, scored on 64 held-out episodes, PID (96 evaluations) plus residual (480) reaches 7.68° mean, against 7.58° for a PID given all 576 evaluations; the residual is better in 7 of 18 airframe-seed pairs and worse in 11, with most of the gap on one airframe. Against the 96-evaluation PID it started from it is better in 14 of 18 but by 0.04° on average, within seed scatter. The airframe ranking is unchanged (Spearman 1.00). A negative result: the error floor is set by gust, sensor noise and motor lag rather than the control-law class in this roll-only model. Limits: evolution strategies rather than PPO, one small network, roll only, six airframes; plant ranges are assumed round numbers carried over from codesign-aero, not measurements.
A figure from its own output
Paper, code and results
More in Agentic co-design of low-cost robots
- Does the strawberry gripper co-design survive the measured range of stem pull-off force?Does the strawberry-gripper co-design of codesign-agri survive measured stem pull-off forces (3.17 N bending and pulling, 13.94 N pulling alone) instead of an assumed 3.5 N? Partly: the optimiser ranking holds in 8 of 10 cells, but the best achievable objective falls from 0.665 to 0.075 as the median pull-off rises from 3.17 to 13.94 N, and at 13.94 N no 40-evaluation run finds a gripper that picks anything
- Do the codesign-agri conclusions survive when its assumed constants change?Does the optimiser ranking of codesign-agri survive a sweep of its 12 invented constants? Mostly: Bayesian optimisation beats CMA-ES beats random search in 82 of 100 worlds, but the best gripper has 2, 3 or 4 fingers depending on stem strength and the nominal winner loses 0.06 J or goes over budget in most worlds
- Does diagnostic feedback help a gripper design loop once the task has headroom?Does diagnostic feedback help a gripper design loop once the scene generator is fixed? Still no: every method gains only 0.00 to 0.05 (best test success 0.85 to 0.90) and the failure-summary and rollout-log readers do not beat random search, CMA-ES or Bayesian optimisation (stylised, rule-based readers, not an LLM).
- Which gripper co-design method finds the best design when designs are scored on 600 scenes instead of 40?Does the ranking of co-design methods survive 600 test scenes? No: re-scoring the 144 final designs of codesign-headroom gives 0.82 to 0.85 true success for every method, random search ties CMA-ES and Bayesian optimisation, and the rollout-log reader trails by 0.03 (interval includes 0)
- Do 24 runs per method rank gripper co-design methods that 8 runs could not?Do more seeds separate the gripper co-design methods? Not yet: with 24 runs per method CMA-ES leads random search by 0.025 (interval -0.007 to +0.056), the rollout-log reader trails by 0.022, and a 0.02 gap would need about 140 runs per method
- Which printable two-finger gripper holds eight different objects for the least plastic, and can an agent beat CMA-ES and Bayesian optimisation at 40 simulations?Which printable two-finger gripper holds eight objects for the least plastic, and can an agent beat CMA-ES and Bayesian optimisation at 40 MuJoCo evaluations? Median best objective 0.991 (Bayesian opt) vs 0.979 (CMA-ES), 0.965 (random) and 0.963 (session agent, one run); the cheapest winners (0.5 g flat fingers) are also the most fragile when object offsets triple. Stylised, no learned policy.
All 27 Agentic co-design of low-cost robots projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.