How few bits can a MAC lane use to classify real handwritten digits before accuracy falls off a cliff?
research/chip-digits
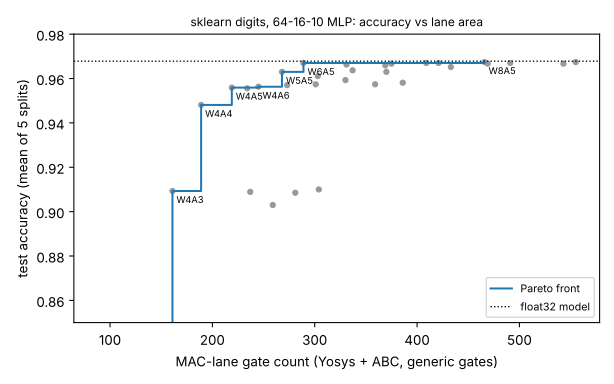
Weight and activation bit-width sweep of a 64-16-10 quantised MLP on the scikit-learn digits data (5 splits), with the MAC lane's gate count from Yosys and its RTL checked against NumPy: 4-bit weights and activations lose about 2 points of accuracy, 5 and 5 about 0.5, below 3 bits it collapses.
What it found
A 64-16-10 ReLU MLP trained on the real scikit-learn digits images (1797 8×8 scans, 70/30 splits, 5 seeds; float test accuracy 96.8%), quantised after training to W-bit signed weights and A-bit unsigned activations (W, A = 2–8, 49 configurations). One multiply-accumulate lane is written in Verilog, simulated in Icarus Verilog and matched to NumPy on 64 real layer-1 dot products per configuration (all 49 agree), and scored with Yosys and ABC in generic gates. Accuracy holds to 96.3% at W5A5 (268 cells, −0.5 points), 94.8% at W4A4 (189 cells, −2.0 points) and collapses at 3 bits or fewer (7978–82% at W3, 31–34% at W2ndash;82% at W3 with 3-bit or wider activations, 3178–82% at W3, 31–34% at W2ndash;34% at W2) or at 2-bit activations; widening beyond 6 bits buys nothing. Lane cells are not monotonic in width (ABC noise). Limitations: one small network and dataset, symmetric max-scaled quantisation with no quantisation-aware training (so the 2–3 bit collapse is a property of that scheme), generic-gate counts not square microns, one lane rather than a full accelerator, no clock, power or layout.
A figure from its own output
Paper, code and results
More in LLM chip design loops
- Can per-channel power-of-two scales make the per-neuron quantiser an integer-exact MAC lane, and what accuracy does it keep at 2 to 4 weight bits?Giving each neuron of the digits MLP its own power-of-two weight scale turns the per-channel rescale into one or two shift stages and keeps the lane integer-exact: at W2A4 the MSE-chosen exponents reach 70.5% (against 62% for per-tensor clipping), but at W3A4 they give 87.9%, below clipping's 90.8%.
- Does clipping, per-channel scaling or quantisation-aware training move the 3-bit cliff of an MLP lane on real digits?MSE-optimal weight clipping lifts the 3-bit-weight digits MLP from 81% to 91% test accuracy at the same MAC-lane hardware and integer-exact; per-channel scales and QAT help at 4 bits (95.7% at W4A4, within 1.1 points of float) but QAT fails at 2 bits.
- What does an all-open RTL flow report for small designs, and can it prove them equivalent?Reproducible open RTL flow (Yosys, Icarus, Verilator): gate count and depth for adders, a multiplier and a FIFO, SAT equivalence of two adders plus a broken-adder control. Gate counts, not silicon.
- Which check catches an RTL bug: lint, random simulation or a formal equivalence proof?What lint, random simulation and a Yosys equivalence proof each catch, on 12 small RTL tasks (companion to
chip-rtl-loop); mutation probe shows 30 of 389 rejected bugs are caught only by the formal proof. Session-written attempts, not an LLM benchmark. - How much does simulation and formal feedback help a proposer repair small Verilog designs?Lint, simulation and formal-equivalence feedback for Verilog repair on nine small tasks; 6/9 pass at round 0 and 9/9 after one round, with the session as proposer (anecdotal, not an LLM benchmark).
- What does a no-model baseline repair when a scripted RTL checker is the only feedback?No-model mutation-repair baseline for a scripted Verilog checker (compile, lint, simulation, SAT miter) on ten small tasks: 9/20 one-fault cases repaired in 60 evaluations; the session agent passed all ten first try, so the feedback loop is unmeasured. Preliminary.
All 40 LLM chip design loops projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.