Does inverse-propensity weighting fix an always-on assistant learning from its own accept/dismiss feedback?
research/ambient-ips
Does inverse-propensity weighting fix an assistant learning from its own accept/dismiss feedback: mostly negative, exploration cost dominates (stylised)
What it found
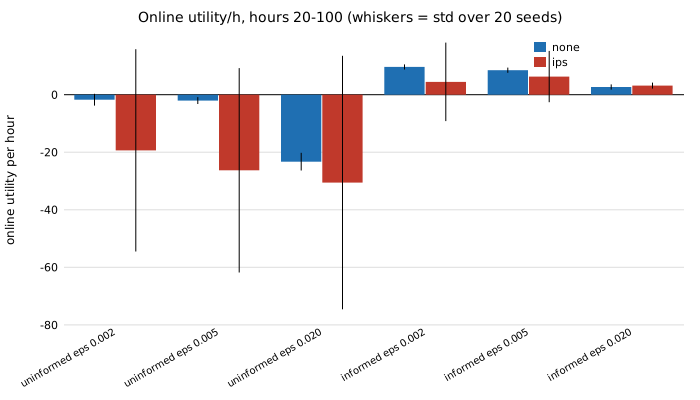
A stylised follow-up to ambient-bandit: the assistant speaks with a known probability (ε-greedy) and refits its model with each labelled window weighted by 1/propensity. Mostly negative: exploration itself costs more utility than the learning gains at every ε tried, weights up to 500 make the weighted fit unstable at small ε (a standard deviation across seeds of tens of utility units per hour), and the weighting did not rescue the uninformed-prior or the drift scenarios. Only at ε = 0.02 with an informed prior is the weighted model slightly closer to the oracle (12.2 vs 11.4 per hour at 100 h, oracle 12.7). Stylised: every distribution is chosen by me.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- Does selection bias actually hurt an always-on assistant that learns only from windows where it spoke?Does selection bias hurt an assistant learning only from windows where it spoke: yes, a lot in this world; a full-information fit reaches the oracle, weighting recovers part (stylised)
- Is the gap in an assistant that learns only from windows where it spoke caused by selection bias or by too few labels?Is the self-selected-feedback gap bias or label volume: mostly bias (a random sample of equal size nearly reaches the oracle); clipped weights help only with an informed prior (stylised)
- Does a doubly robust estimator fix learning from an assistant’s own self-selected feedback?Does a doubly robust estimator beat IPS on an assistant's self-selected feedback: no, a stylised negative result; its pseudo-labels carry 1/ε residuals and are worse than the biased fit except with an informed prior.
- Does capping the inverse-propensity correction rescue doubly robust learning from an assistant’s own feedback?Does capping the inverse-propensity correction rescue doubly robust learning from an assistant's own feedback: with an informed prior yes (the collapse at ε = 0.002 goes from 0.26 to about 12 utility/h), with an uninformed prior no; stylised, simulated only.
- Does cross-fitting the outcome model help capped doubly robust learning from an assistant’s own feedback?Does fitting the doubly robust outcome model out-of-sample (2-fold cross-fitting) help the capped correction: no, a negative result; differences are within seed noise or worse, and the unclipped collapse at ε = 0.002 persists (1.53 vs 0.26 utility/h); stylised, simulated only.
- Can the doubly robust cap be chosen by validation on an assistant’s own logs?Can the capped doubly robust cap be chosen by 4-fold IPS validation on the log: with an informed prior it matches the best fixed cap within seed noise, with an uninformed prior it does not rescue learning; stylised, simulated only.
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.