Does the accumulator-read bug found in accel-gatedmux also inflate accel-planebatch's weight-stationary area?
research/accel-planemux
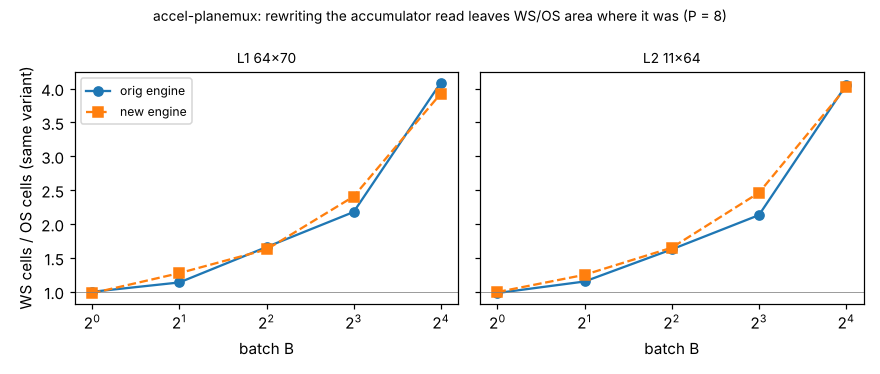
Does accel-gatedmux's accumulator-read bug also inflate accel-planebatch's WS area? No: the rewritten engine is bit-exact with identical counts and its area is within -3 % to +12 % with no trend (WS/OS 1.62 vs 1.66 at B = 4); the earlier verdict stands.
What it found
accel-gatedmux found that a variable-index accumulator read made the weight-stationary (WS) engines of accel-gatedrtl 17 to 28 % too large. The batched engine of accel-planebatch has the same index. Rewriting its read as an AND-OR over constant indices and its write as decoded enables, and re-running all 40 points (two accel-kws layers, batch 1 to 16, P = 8), gives bit-exact outputs and identical cycles and fetch counts, with WS area between −3 % and +12 % of the original and no trend in batch (WS/OS cells at B = 4: 1.66 before, 1.62 after). Negative: the earlier verdict stands, because here the accumulators are a Verilog array that Yosys already muxes per entry. Generic-gate cells from one mapper run per point, which moves about 3 % by itself.
A figure from its own output
Paper, code and results
More in Task-specific AI accelerators
- How many MAC lanes of a keyword-spotting matrix engine fit on a small open-toolchain FPGA, and which dataflow is fastest there?Accel-plane's output-stationary and reduction-tree engines at 1 to 32 lanes through Yosys and nextpnr-ice40 on an iCE40 UP5K: output-stationary at 16 lanes is fastest that fits (10.2 us per 64x70 product, 2,942 of 5,280 cells); DSP mapping cuts logic 13 to 41% but fails to place beyond 8 lanes. Stylised, synthesis only.
- Does a quantised surrogate make a design search cheaper in finite-element solves than searching with the simulator alone?Does a quantised surrogate make a design search cheaper in FE solves than searching with the simulator alone? At 150 FE evaluations a surrogate-assisted loop is 2.3 to 2.8 % from a best-known design against 6 to 8 % for an FE-only evolution strategy and 14 to 20 % for random search (float and 6-bit surrogates indistinguishable; stylised, 8 seeds).
- With a locking-free finite-element simulator, how much surrogate error can a design loop tolerate?With a locking-free Q6 finite-element simulator, how much surrogate error can a design loop tolerate? At 64x8 the surrogate adds 0.5 to 0.8 points to the FE's 2.3 % error; with no safety margin a min-mass screen breaks the limit in 24 to 33 % of cases, with a 5 to 10 % margin 2 to 9 %. Stylised.
- When the beam simulator is a 2D finite-element model, does a quantised surrogate (and an accelerator for it) pay?When the beam simulator is a 2D plane-stress FE model, does a quantised MLP surrogate (and an accelerator) pay? The energy break-even is met (34x at 32x4 mesh, 319x at 64x8, assumed constants), and the surrogate's 2 % error against its FE is small beside the FE's own 9 % discretisation error; but the locking Q4 simulator is itself inaccurate. Stylised.
- Can a quantised MLP surrogate of a finite-element beam beat the beam's own model-form error, and when would an accelerator for it pay?Can a quantised MLP surrogate of an FE cantilever beat the Euler-Bernoulli vs Timoshenko gap (0.09 % median), and would an accelerator pay? No: float error is 1.7 % (18x the gap), 6-bit QAT stays within 0.3 points of float, and the surrogate only beats the solver above ~1,600 simulator flops. Stylised.
- Does a small control network need an accelerator to meet the control-rate deadline?Can a small behaviour-cloned control network meet the control-rate deadline on a microcontroller or a P-lane accelerator for a two-link arm? Stylised and preliminary: the int8 policies track 300+ times worse than their teacher, so policy accuracy, not hardware speed, is the limit; the latency model (assumed constants) shows hardware matters only above about 10 kHz.
All 40 Task-specific AI accelerators projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.