Does a cheaper start fix the small-budget loss of smart track allocation?
research/swe-warmstart
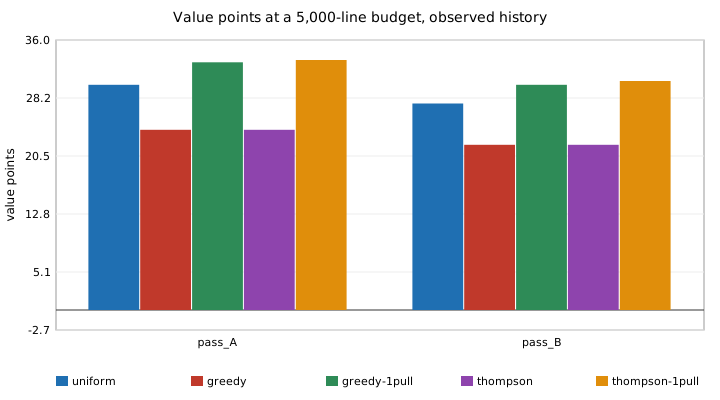
Does a cheaper start fix the small-budget loss of smart track allocation? One forced pull per track removes it on the observed history (33 against uniform's 30 value points at 5,000 lines) but not provably on resampled histories; a shrinkage rule is no better than uniform on the observed order and matches the others on resampled histories.
What it found
swe-decay found greedy and Thompson track allocation losing to uniform at a 5,000-line budget (24 against 30 value points) because two forced pulls per track ate it. Here each track is pulled once, or a shrinkage rule uses no forced pulls. On the observed history one pull each removes the loss (pass A: 33.0 and 33.3 against uniform 30.0) but costs a few points at 20,000 lines in pass B; shrinkage greedy is no better than uniform on the observed order, matches the others on resampled histories, and is insensitive to its prior size. On 200 block-bootstrapped histories every start rule’s 5,000-line interval over uniform still includes zero. Stylised: lines of code stand in for cost, the value scores agree weakly, and no live trial was run.
A figure from its own output
Paper, code and results
More in The software-engineering loop
- Where do agent runs say the documentation hurts, and do the same complaints keep coming back?Where do agent runs say the documentation hurts? 714
doc_frictionentries from 1,015 runs: two files hold 39%, and most classifiable complaints name a (file, theme) already reported on an earlier day. Preliminary. - Do documentation complaints in agent run records repeat more than chance?Do documentation complaints repeat more than chance? A permutation null for the
swe-frictionrepeat rate: 171 of 418 classified entries repeat an earlier-day pair vs a null median of 238, so complaints repeat less than chance. Preliminary. - Which test input should you use to calibrate a mass-spring-damper twin?Which test input should you use to calibrate a mass-spring-damper twin? A resonant sine gives the lowest held-out prediction error (3.1e-4 vs 1.1e-3 for a step) yet the worst Fisher condition number (527 vs 56 to 114); fitted spreads sit within 0.83 to 1.09 of the Cramér-Rao bounds. Stylised, preliminary.
- What can the run log measure about the agent loop today?What can the run log measure about the agent loop today? Cost fields are present in at most 1% of 189 runs, a third of listed projects are follow-up families, and every recorded CI-failure count is zero. Preliminary first step of track 10.
- What does an agent run cost, and which runs cost the most?What does an agent run cost, and which cost the most? 355 priced runs (14 to 18 October): median $0.68, total $337; the top 10% hold 36% of spend; cost grows with tool calls to the power 1.18 (preliminary; API-equivalent estimates).
- What do agent runs record going wrong, and does it relate to partial outcomes or cost?What do agent runs record going wrong? 17% of 1,027 runs record an error (24.5% of research runs); environment 28%, own mistakes 21%, collisions 17%; runs with an error end partial twice as often (12.6% vs 6.0%) and cost about twice as much. Preliminary: keyword classifier, self-reported.
All 43 The software-engineering loop projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.