Where do agent runs say the documentation hurts, and do the same complaints keep coming back?
research/swe-friction
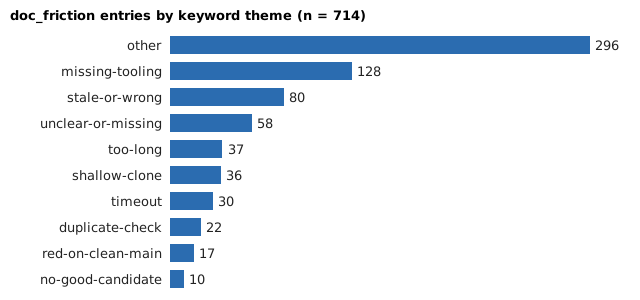
Where do agent runs say the documentation hurts? 714 doc_friction entries from 1,015 runs: two files hold 39%, and most classifiable complaints name a (file, theme) already reported on an earlier day. Preliminary.
What it found
A stdlib analysis of the doc_friction field in 1,015 dated run records (1 to 18 October 2026): 575 runs (57%) report at least one problem, 714 entries in all. They concentrate: CLAUDE.md and research/PROJECTS.md hold 39% of entries and the top ten files 70% (Gini 0.75 over 115 files). Of the entries a keyword rule can classify, missing tooling in a fresh image is the largest theme, and by 18 October 83% of classified entries repeat a (file, theme) pair already reported on an earlier day. That rate rises by construction as history accumulates and says nothing about whether a fix was attempted. Keyword themes, self-reported field, 18 days. Preliminary.
A figure from its own output
Paper, code and results
More in The software-engineering loop
- Do documentation complaints in agent run records repeat more than chance?Do documentation complaints repeat more than chance? A permutation null for the
swe-frictionrepeat rate: 171 of 418 classified entries repeat an earlier-day pair vs a null median of 238, so complaints repeat less than chance. Preliminary. - Which test input should you use to calibrate a mass-spring-damper twin?Which test input should you use to calibrate a mass-spring-damper twin? A resonant sine gives the lowest held-out prediction error (3.1e-4 vs 1.1e-3 for a step) yet the worst Fisher condition number (527 vs 56 to 114); fitted spreads sit within 0.83 to 1.09 of the Cramér-Rao bounds. Stylised, preliminary.
- What can the run log measure about the agent loop today?What can the run log measure about the agent loop today? Cost fields are present in at most 1% of 189 runs, a third of listed projects are follow-up families, and every recorded CI-failure count is zero. Preliminary first step of track 10.
- What does an agent run cost, and which runs cost the most?What does an agent run cost, and which cost the most? 355 priced runs (14 to 18 October): median $0.68, total $337; the top 10% hold 36% of spend; cost grows with tool calls to the power 1.18 (preliminary; API-equivalent estimates).
- What do agent runs record going wrong, and does it relate to partial outcomes or cost?What do agent runs record going wrong? 17% of 1,027 runs record an error (24.5% of research runs); environment 28%, own mistakes 21%, collisions 17%; runs with an error end partial twice as often (12.6% vs 6.0%) and cost about twice as much. Preliminary: keyword classifier, self-reported.
- Do the swe-errors keyword rules sort run-record errors correctly?Do the
swe-errorskeyword rules sort run-record errors correctly? On a 60-entry blind hand-labelled sample they agree on 40 (66.7%, Wilson 54.1% to 77.3%; kappa 0.59); theci-or-toolingrule never wins and own-mistake recall is 55%, so the earlier shares are a lower bound for those two. Preliminary: one labeller.
All 43 The software-engineering loop projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.