What happens to a regression coefficient when the regressor is an LLM's code?
research/qual-regression
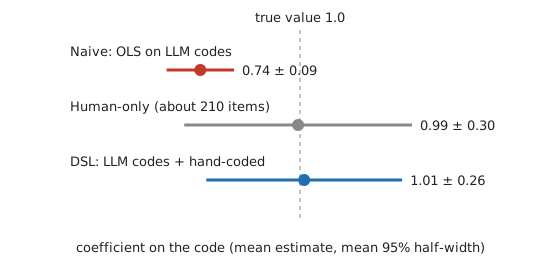
What happens to a regression coefficient when the regressor is an LLM's code? Naive OLS gives 0.74 for a true 1.00 (0% coverage) and biases a perfectly measured covariate when coder error depends on it; DSL with ~210 hand-coded items fixes both (coverage 94–97%) but narrows the coded coefficient's interval only 14%; per-class PPI fixes 3-class shares. Simulated coders.
What it found
Regressing an outcome on an LLM's codes attenuates the coded variable's coefficient (0.74 for a true 1.00, interval coverage 0% in 300 simulated studies) and, when the coder's error depends on another covariate, biases that perfectly measured covariate too (0.467 against 0.50, coverage 60%). Design-based supervised learning (DSL) with about 210 hand-coded items drawn at a known 7% rate recovers both (1.01 and 0.50, coverage 94–97%) but narrows the coded coefficient’s interval by only 14%. For a 3-class code, naive class shares are off by up to 8.5 points with 0% coverage; per-class PPI covers 95.5–97%. Simulated coders only; no real LLM was run.
A figure from its own output
Paper, code and results
More in Machine learning on qualitative data
- Does the prediction-powered correction work on real hand-coded text?Does the prediction-powered correction work on real hand-coded text? On 3,188 GoEmotions comments a naive-Bayes coder (kappa 0.14) is wrong on prevalence (13% against 25%, 0% coverage) and overstates a length gap six-fold; PPI repairs both but is wider than hand-coding alone. Not an LLM (no key).
- How much hand-coding can an LLM coder replace, with a valid interval, when its error differs by group and the category is rare?Research programme: valid inference from LLM-coded qualitative data under group shift and rare categories; on 44,485 real tweets a pooled PPI interval covers as little as 67% when the audit's language mix differs from the corpus, a language-stratified one 94 to 96%
- How well does an LLM-style coder count negative emotion in real comments, and does the correction still pay?How well does an LLM-style coder count negative emotion in real comments? The Claude session agent, coding 300 GoEmotions comments blind, flags 44% as negative against a human 23% (opposite error to the classical stand-ins); accuracy 0.71 matches naive Bayes and trails a word list, and prediction-powered inference stays valid but 29% wider than hand-coding. One reader, not an API model.
- Does an automated coder's error differ across languages, and how much does that move group comparisons?Does an automated coder's error differ across languages? On 44,485 real tweets in Hausa, Igbo, Nigerian Pidgin and Yoruba, an English word-list coder and an English-trained classifier read almost none of the negative sentiment in Hausa, Igbo and Yoruba (sensitivity 0.4–11%), flipping some language gaps' sign (Hausa–Yoruba +10.6 points true, −6.5 reported); PPI keeps coverage at 93–96% but is never narrower than hand-coding. Not an LLM (no key)
- How big must a hand-coded audit be before you can trust a coder's counts?How big must a hand-coded audit be before you can trust a coder's counts? On 3,188 GoEmotions comments, a tight equivalence test never passed the coder and a loose one passed it too often (coverage 0.35 at 1,600 audited items). Not an LLM; one corpus.
- Do a dozen codebook codes predict better than bag-of-words when labels are scarce?Do a dozen codebook codes predict better than bag-of-words when labels are scarce? On GoEmotions, 12 word-list codes reached 0.65 AUC at 100 labels against 0.56 for bag-of-words, and still led at 1,600 (0.75 against 0.67). Word lists, not an LLM; no learned embedding tested.
All 23 Machine learning on qualitative data projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.