Do a dozen codebook codes predict better than bag-of-words when labels are scarce?
research/qual-features
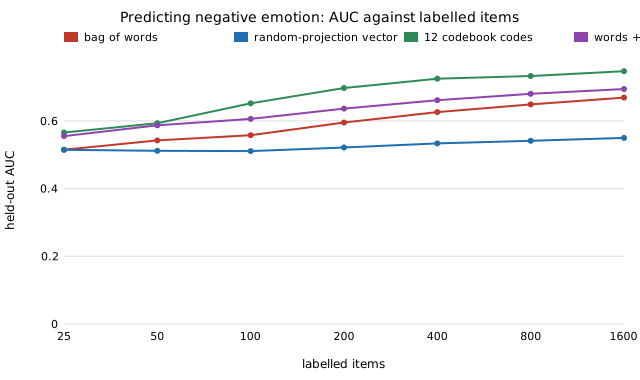
Do a dozen codebook codes predict better than bag-of-words when labels are scarce? On GoEmotions, 12 word-list codes reached 0.65 AUC at 100 labels against 0.56 for bag-of-words, and still led at 1,600 (0.75 against 0.67). Word lists, not an LLM; no learned embedding tested.
What it found
On GoEmotions comments (predict a negative-emotion label, AUC on 1,500 held-out items), a logistic model on 12 word-list codebook codes plus log length beats bag-of-words at every labelling budget from 25 to 1,600 items: 0.65 against 0.56 AUC at 100 labels and 0.75 against 0.67 at 1,600, with bag-of-words still gaining. Adding the codes to the bag of words lands between the two, and a 64-dimension random projection of the words is near chance (0.55 at 1,600). The codes are word lists, not an LLM, and a learned sentence embedding was not tested; one corpus, one label, 12 subsets per size.
A figure from its own output
Paper, code and results
More in Machine learning on qualitative data
- Do LLM-style qualitative codes predict outcomes better than bag-of-words at the same labelling budget?Do LLM-style qualitative codes predict outcomes better than bag-of-words at the same labelling budget? On 5,313 GoEmotions comments, not for a reply-vs-top-level outcome: emotion codes (human, an upper bound) reach AUC 0.527 against 0.557 for words and 0.595 for LSA, and 5% coder error erases their gain. All sets are weak; not an LLM.
- Does a hand-coded audit protect a group gap when it only checks the overall count?Does a hand-coded audit protect a group gap when it only checks the overall count? On 3,188 GoEmotions comments, a coder with zero overall bias still distorted a short-vs-long gap by 0.20, and the overall-bias gate covered the gap 0.4% of the time at 1,600 audited items. Not an LLM; one corpus.
- Can you estimate a group gap from an audit that hand-codes only a few of the coder's negatives?Can you estimate a group gap from an audit that hand-codes only a few of the coder's negatives? Not usefully: 0.9-wide intervals at 5 items, and a plain random audit (0.23 wide) beats the design. Pooling the groups' negatives covers 3%. 3,188 GoEmotions comments, not an LLM.
- If a hand-coded audit finds no bias in a coder, can you trust its counts?If a hand-coded audit finds no bias in a coder, can you trust its counts? On 3,188 GoEmotions comments, an audit-then-trust rule covered the truth in 8% of draws for a coder 2.6 points off, while always applying the prediction-powered correction covered 94–97%. Not an LLM; one corpus.
- Does a low audit rate for coder-negatives pay when the coder has high recall?Does a low audit rate for coder-negatives pay when the coder has high recall? On 3,188 GoEmotions comments the best share falls with recall (50%, 20%, 2%), but the narrowest interval (0.115–0.119 at 200 items) only matches a random audit with no coder (0.1195). Not an LLM.
- Do hypotheses about what separates two sets of documents survive a held-out check?Do hypotheses about what separates two sets of documents survive a held-out check? On 5,313 GoEmotions comments a word-counting proposer's effects are 7.6× too large at 100 discovery comments (1.5× at 2,000); a BH check on 3,000 held-out comments confirms almost nothing with shuffled labels, but 36–59% of confirmed hypotheses are the label's own vocabulary. Not an LLM proposer.
All 23 Machine learning on qualitative data projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.