How many of the coder's negatives must you hand-code to recover the positives it missed?
research/qual-negaudit
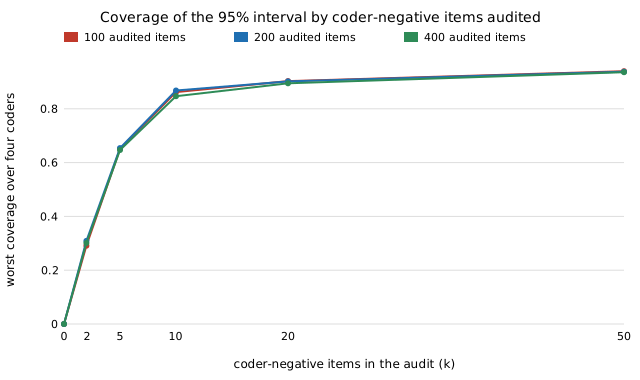
How many of the coder's negatives must you hand-code to recover the positives it missed? On 3,188 GoEmotions comments, about 50: coverage was 0.29 with 2, 0.87 with 10 and 0.94 with 50, whatever the audit's total size. Not an LLM; one corpus.
What it found
On 3,188 real GoEmotions comments, four automated coders (three cut-offs of a naive-Bayes classifier and a word list; not LLMs) and a hand-coded audit that puts k items on coder-negatives and the rest on coder-positives, weighted back by stratum share: the positives-only audit (k = 0) is biased by the coder's miss rate (−0.128 to −0.169 on a true 0.252) and covers the truth in 0 of 1,000 draws. Auditing any coder-negatives removes the bias, but the 95% interval is short of nominal until about 50 coder-negative items (worst coverage over coders 0.29–0.31 at k = 2, 0.85–0.87 at k = 10, 0.94 at k = 50), and the width at k = 50 is 0.15–0.19 whether the audit has 100 or 400 items in total. Two negatives is worse than none by RMSE (0.216 against 0.152). One code, one corpus, one split; Wald intervals ignoring the finite-population correction.
A figure from its own output
Paper, code and results
More in Machine learning on qualitative data
- Which confidence interval is right when only 5 to 20 of the coder's negatives are hand-coded?Which confidence interval is right when you hand-code only 5 to 20 of the coder's negatives? Not Wald: 0.63 coverage at 5 items against 0.94 for Wilson or Jeffreys on 3,188 GoEmotions comments. Not an LLM; one corpus.
- Does equal-numbers stratified auditing still match the optimal split when the coder errs more in the rare group?Does equal-numbers stratified auditing still match the optimal split when the coder errs more in the rare group? On 3,188 GoEmotions comments, injecting up to 30% extra label flips in the rarest 11% group moved the optimal audit share only from 0.53 to 0.56, and equal numbers stayed within 0.7% of optimal width. Not an LLM.
- Does a coder's error depend on writing register, and can a hand-coded sample tell?Does a coder's error depend on writing register, and can a hand-coded sample tell? On 3,188 GoEmotions comments, error differs by 1.9 points (naive-Bayes) or none (lexicon) between formal and informal text, yet the naive register gap is three times too large; an audit with up to 800 hand-coded items flags it no more often than chance. Not an LLM (no key); register is a proxy, not a dialect.
- Should the hand-coded audit for a group gap be stratified by group?Should the hand-coded audit for a group gap be stratified by group? On 3,188 GoEmotions comments, it made no difference for a 36% group and a random audit gave intervals 1.7 times as wide for an 11% group at 100 items. Equal numbers per group matched the optimal split. Not an LLM; one corpus.
- Can you do machine learning on qualitative data with an LLM, and when can you trust the numbers?Can you do machine learning on qualitative data with an LLM, and when can you trust the numbers? Simulated LLM coders with known error: an 89%-accurate coder (κ = 0.72) understates a 30% code at 26% with 0% interval coverage, and when it reads one group's answers less accurately the naive group gap has the wrong sign (+3.6 against −4 points, "significant" 80% of the time). Prediction-powered inference with 200 hand-coded answers per group removes the bias and narrows intervals 23–26% against hand-coding alone, but is wider below ~80% coder accuracy. Stdlib tool (κ, Krippendorff's α, PPI). Simulated, no real model.
- What happens to a regression coefficient when the regressor is an LLM's code?What happens to a regression coefficient when the regressor is an LLM's code? Naive OLS gives 0.74 for a true 1.00 (0% coverage) and biases a perfectly measured covariate when coder error depends on it; DSL with ~210 hand-coded items fixes both (coverage 94–97%) but narrows the coded coefficient's interval only 14%; per-class PPI fixes 3-class shares. Simulated coders.
All 23 Machine learning on qualitative data projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.