How do you pay for effort when nobody knows the truth?
research/peer-prediction-effort
Peer prediction without ground truth: output agreement pays 1.0 for laziness vs 0.68 for honesty, Dasgupta–Ghosh payoff 2p(1-p)g_i g_j exact, effort as a coordination game with threshold c/(2p(1-p)κ²), and closed-form gold-check rate √(c·g_H/G).
What it found
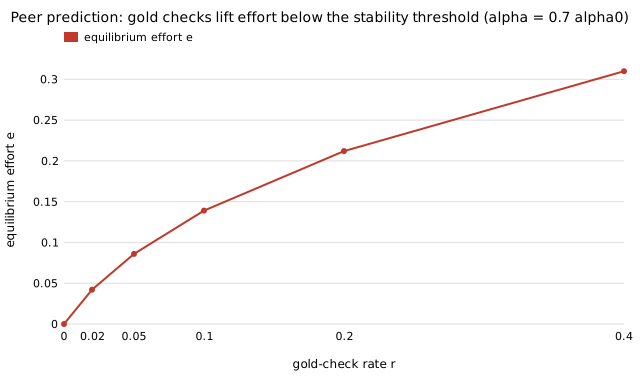
Peer prediction for unverifiable labelling and judging work: output agreement pays 1.0 for always answering the majority label versus 0.68 for honesty, the Dasgupta–Ghosh payoff is exactly 2p(1−p)gigj, effort becomes a coordination game with a closed-form threshold (12.8× higher for rare-positive tasks), and a cost-optimal gold-check rate √(c·gH/G) removes the shirking equilibrium. Stylised.
A figure from its own output
Paper, code and results
More in Effort & peer prediction
- Does agreement pay reward shared laziness?Peer prediction when lazy verifiers share a default answer: agreement pay is
2G·Cov, effort is a coordination game with thresholda*=(k/2G+s)/(pq+s), the all-lazy equilibrium always exists and pays as much as honesty when the default matches the prior, and gold checks needing more mass than the honest pay close it. - How noisy is peer-prediction pay with finitely many tasks?Finite-sample noise in multi-task peer prediction: the plug-in payment is 2× the sample covariance with an exact variance (matches enumeration), √2 less noisy than fresh penalty tasks, pays a constant reporter 0, and a lazy coin still earns
≈σ/√(2π)under limited liability; deductibles and detection/ranking sample sizes in closed form. - When most verifiers miss a fault, who should be believed?Surprisingly-popular verdicts for rare-but-diagnostic signals: majority errs 0.84 on faulty jobs at n=101 when detection is 0.45, SP is an exact fraction threshold
v/(1−u+v)(2.1×10⁻⁵ error, 47 votes for 10⁻³ vs Bayes 36), a wrong believed prior wrecks finite-n accuracy, a wrong believed detector breaks the limit, Byzantine breakdown at exactly 13.6%. - Why should the first verifiers be sealed?Sequential verifiers who see earlier verdicts herd: wrong-cascade probability exactly
(1−a)²/(a²+(1−a)²), cascade after2/(a²+(1−a)²)signals, accuracy capped at 0.845 (a=0.7) versus ≈1 for an independent majority, and a sealed first batch of ≥3 lifts the cap (0.875 at m=3, 0.949 at m=11); checked against Bayesian agents. - When should a paid verifier stop checking?Verifiers who choose when to stop checking under a proper score: optimal policy is a symmetric threshold (matches dynamic programming), closed-form accuracy
1/(1+((1−a)/a)^k)and costk(2p_k−1)/(2a−1), participationκ ≥ 4c/(2a−1)², and adaptive stopping matches fixed-sample accuracy with 2–3× fewer checks. - Peer-prediction markets for decentralized ML training verificationPeer-prediction and prediction-market mechanisms for verifying decentralized ML training, with adversarial evaluation.
All 9 Effort & peer prediction projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.