On a swing-up task where friction matters, does a digital twin's detectability predict what tuning on it costs?
research/mimic-twinswing
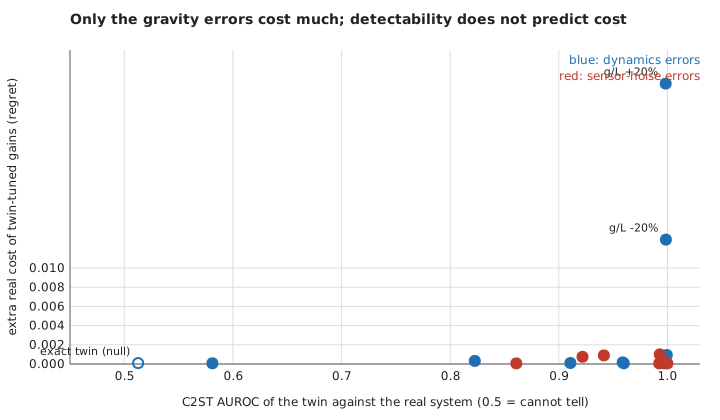
On a swing-up task where friction matters, does a twin's detectability predict what tuning on it costs? Stylised pendulum: only the two gravity-error twins cost much (3.7% and 8.3% extra real cost); 13 others cost under 0.3% at C2ST AUROC 0.51 to 1.0. Preliminary, simulated only.
What it found
Follow-up to mimic-twinregret on the same stylised pendulum, now with a torque limit below gravity so the controller must pump energy against friction, then catch the top with PD. Controllers are tuned on 15 wrong twins (60-point grid, 12 seeds) and scored on held-out real starts. Only the two gravity-error twins cost much: g/L +20% adds 8.3% to the best real cost and g/L −20% 3.7%; every other twin is under 0.3%, including no sensor noise, no Coulomb friction and doubled viscous friction, at C2ST AUROC up to 1.0. Spearman AUROC vs regret ρ = 0.16 (p = 0.57), paired RMSE vs regret 0.43 (p = 0.11). Stylised, one task, coarse grid; best gain on the grid edge for several twins.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- Does a finer controller grid change which wrong digital twins cost something on a swing-up task?Does a finer controller grid change which wrong pendulum twins cost something on the swing-up task? No: the same two gravity-error twins cost 3.8% and 6.1%, the rest under 0.3%; detectability vs regret ρ = 0.38 (p = 0.16). Preliminary, simulated only.
- Does a wider gain grid, or a controller that uses the twin's gravity, change which wrong digital twins are costly?Does a wider gain grid, or a controller that uses the twin's gravity, change which wrong pendulum twins are costly? Gravity errors stay the costly ones; giving the controller the twin's g/L made g/L −20% regret 13 times larger (0.013 to 0.177). Preliminary, simulated only.
- Does domain randomization over a wrong digital twin cut the controller regret of tuning on one wrong twin?Does tuning a controller on a spread of randomized twins cut the regret of tuning on one wrong twin? Stylised pendulum: it brings the no-noise twin's regret from 0.0098 to 0.00006, but a very wide range raises a doubled-noise twin's worst-seed regret 7.5-fold. Preliminary, no LLM.
- Does randomizing only the sensor-noise level of a wrong digital twin keep domain randomization's rescue without its blow-up?Does randomizing only the noise level of a wrong twin keep domain randomization's rescue without its blow-up? Stylised pendulum: the no-noise twin's regret goes 0.0098 to 0 and stays small at a wide range (worst seed 0.0015 vs 0.042 for all-four), but friction and gravity errors are not helped. Preliminary, no LLM.
- How many real trajectories does a classifier test need to flag a wrong digital twin, and are the twins it flags the ones that cost a controller?How many real trajectories does a classifier test need to flag a wrong digital twin, and are the twins it flags the ones that cost a controller? Stylised pendulum: all six twins with controller regret of at least 0.001 are flagged by 80 real trajectories, and so are three that cost nothing. Preliminary, simulated only.
- Does a second turn make a plainly prompted LLM easier to spot in dialogue?Does a second turn make a plainly prompted LLM easier to spot in dialogue? A prompt-free n-gram detector gets AUROC 0.93 on one imitated user turn and 0.98 on two, on 400 OpenAssistant threads with a 0.5B imitator. Stylised baseline, no prompt optimised.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.