Can an imitator that changes its own code fool a human-vs-bot cursor detector, and does shared feedback help either side?
research/mimic-cursor
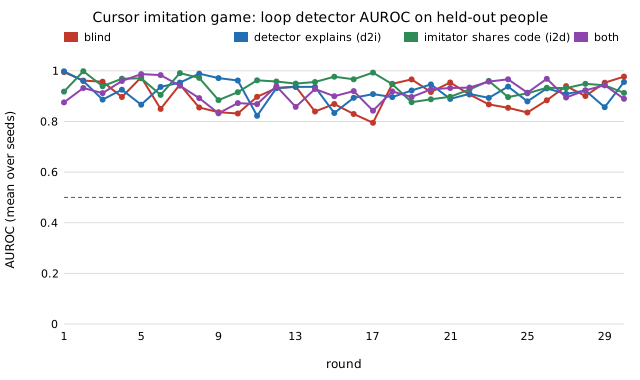
Can an imitator that changes its own code fool a human-vs-bot cursor detector, and does shared feedback help? On DUX cursor strokes of 46 people, a held-out reference detector catches every final imitator at AUROC 0.99 to 1.00 in all four feedback conditions; two-way sharing gave the strongest detectors in cross-play (0.81 vs 0.70 blind, interval includes 0), and an 8x larger search stops at 0.88, the level of replaying real strokes. Preliminary.
What it found
Browser use, the first subject of the adversarial-imitation track beyond writing. Cursor strokes of 46 people from DUX (CC-BY-4.0) against an imitator built from code components and a detector that picks 3 of 11 feature functions, 4 feedback conditions × 8 seeds × 30 rounds at equal budget. A reference detector the loop never saw catches every final imitator at AUROC 0.99 to 1.00; detector explanations and shared imitator code did not make a better imitator. Detectors trained with two-way sharing did best against other runs’ imitators (cross-play AUROC 0.81 vs 0.70 blind), but the paired interval includes zero. An 8× larger search ends at 0.88, no better than replaying a real stroke, so the component library is the limit. Preliminary: one web form, 8 seeds, no model-written code.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- Can a generator imitate a person's webcam emotion signals well enough to fool a detector?Can a generator imitate a person's webcam emotion signals well enough to fool a detector? On DUX Affectiva scores of 46 people, every fixed generator and every loop-tuned imitator is caught at AUROC 0.997 or higher by a detector the loop never saw; only replaying real windows gets close to chance (0.61). Preliminary.
- Does giving a webcam-signal generator real heavy tails and bursts fool a detector?Does giving a webcam-signal generator real heavy tails and bursts fool a detector? No: copula and quiet/burst generators still separate from held-out people at AUROC 1.000 (8 seeds); restoring per-window level and spread brings level and spread to near chance, but extremes (0.995) still give it away; copying a real window's value set (G6) puts those at chance too, yet all-groups AUROC stays 0.998 on temporal structure.
- Is the prompted detector's inversion (AUROC below 0.5 on machine text) a model-size effect?Does a bigger Qwen make a better human-vs-machine detector? Partly: plain-prompt AUROC rises from 0.278 (0.5B) to 0.329 (1.5B), but 1.5B is still below chance in 84% of family-by-prompt cells.
- Can a small open code model write a cursor-stroke generator that fools a human-vs-bot detector?A 1.5B code model rewrites the cursor generator against the mimic-cursor detector: only 25 to 29% of its candidates run, and the reference detector stays at AUROC 1.000, tied with the component search at the same 24-candidate budget (one seed, preliminary negative).
- Does a human-vs-machine text detector still work on a language model, or a decoding setting, it never saw?Does a prompt-free detector transfer to unseen generators? Mostly: char+word n-grams keep AUROC 0.97 to 0.98 on a held-out chat model and 0.94 across a greedy-to-sampling shift; function-word cues alone drop to 0.69 to 0.85.
- Do prompts that fool a prompted LLM detector also fool detectors that use no prompt?Do the mimic-loop imitator prompts fool detectors they never saw? No: matched on length, all 26 testable prompts are still caught (n-gram AUROC 0.83 to 0.96, Binoculars-style 0.84 to 1.00); low raw scores come from text length.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.