Is the prompted detector's inversion (AUROC below 0.5 on machine text) a model-size effect?
research/mimic-anycontext-size
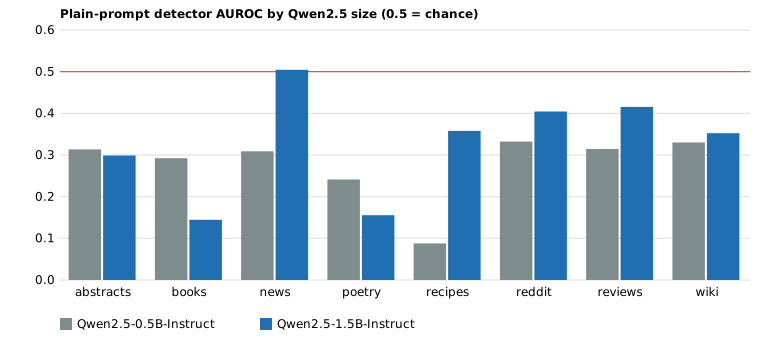
Does a bigger Qwen make a better human-vs-machine detector? Partly: plain-prompt AUROC rises from 0.278 (0.5B) to 0.329 (1.5B), but 1.5B is still below chance in 84% of family-by-prompt cells.
What it found
Replays the first four detector prompts of mimic-anycontext-prompt on its 30 human + 30 RAID machine test texts in each of eight families, with Qwen2.5-0.5B-Instruct and Qwen2.5-1.5B-Instruct (Yes/No logit difference, single-text mode). Mean AUROC of the plain prompt is 0.278 at 0.5B and 0.329 at 1.5B; the best of the four prompts reaches 0.296 and 0.389. At 1.5B, 27 of 32 family-by-prompt cells are still below 0.5 (all 32 at 0.5B); only news is near chance (0.504). The sign-flipped score would average 0.72 and 0.67. The 0.5B plain-prompt mean (0.278) matches the earlier project. The gain is uneven: recipes and news improve, books and poetry get worse. Limitations: two sizes of one model family, four prompts, 30+30 texts per family (family AUROC standard error about 0.06), one seed, no selection step. Nothing here is an adapted imitator.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- Can a small open code model write a cursor-stroke generator that fools a human-vs-bot detector?A 1.5B code model rewrites the cursor generator against the mimic-cursor detector: only 25 to 29% of its candidates run, and the reference detector stays at AUROC 1.000, tied with the component search at the same 24-candidate budget (one seed, preliminary negative).
- Does a human-vs-machine text detector still work on a language model, or a decoding setting, it never saw?Does a prompt-free detector transfer to unseen generators? Mostly: char+word n-grams keep AUROC 0.97 to 0.98 on a held-out chat model and 0.94 across a greedy-to-sampling shift; function-word cues alone drop to 0.69 to 0.85.
- Do prompts that fool a prompted LLM detector also fool detectors that use no prompt?Do the mimic-loop imitator prompts fool detectors they never saw? No: matched on length, all 26 testable prompts are still caught (n-gram AUROC 0.83 to 0.96, Binoculars-style 0.84 to 1.00); low raw scores come from text length.
- Can a learned Markov chain over a person's webcam frames fool a detector?Can a Markov chain over a person's frames fool a detector? No: chains with 8, 32 or 128 states, fitted on one person or on everyone, emitting state centres or real frames, are caught at AUROC 1.000 (one cell 0.999), where stitching the same real frames in 50-frame blocks scored 0.57 to 0.65.
- Does fitting a webcam-signal generator to one person fool a detector that has seen that person?Does fitting to one person help? Copying a person's own earlier windows is caught at AUROC 0.59 to 0.65 on their later windows; copying other people is 0.58 to 0.91, and 0.93 to 0.97 once the detector knows the person; a fitted parametric generator is caught at 1.000 either way.
- Does giving a Markov chain dwell times or a second-order memory let it fool a webcam-signal detector?Does giving a chain over a person's frames dwell times or second-order memory help? No: semi-Markov and second-order chains (8 or 32 states, own or pooled fit, centre or real-frame emission) are all caught at AUROC 0.999 to 1.000.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.