A twin whose wind gusts are matched to the logged variance each step: how wrong is the position variance of a PD-held vehicle, and does matching the spectrum instead fix it?
research/gust-twin
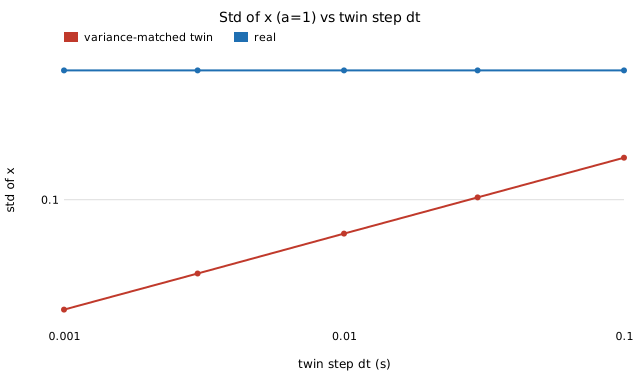
A twin whose wind gusts are iid per step with the logged variance: real position variance is s²(a+k_d)/(k_d k_p(a²+a k_d+k_p)), the twin's is 141× smaller at a=1, dt=0.01 and scales as dt, its 1e-3 margin is exceeded 78% of the time, and a spectrum-matched white twin is always conservative.
What it found
Real gust: Ornstein–Uhlenbeck with rate a and variance s2; exact real variance s2(a+kd)/(kdkp(a2+akd+kp)). A twin drawing iid gusts per step has variance s2dt/(2kdkp): 141× too small at a=1, dt=0.01 (270× at a=0.05), a standard deviation scaling as √dt, and a 10−3 margin that the real system exceeds 78% of the time. A spectrum-matched white twin is always conservative, real/twin = a(a+kd)/(a2+akd+kp) < 1 (0.71 at a=1). Fitting the OU rate from logged wind recovers the real variance (within 1% at 105 samples). Stylised: linear loop, Gaussian gusts, no wind data.
A figure from its own output
Paper, code and results
More in Digital twins & sim-to-real
- A free-space radar twin ignores ground-bounce lobing: how wrong is it, and can a two-ray twin with a slightly wrong target height be worse?Free-space radar twin vs two-ray ground-bounce lobing: detection fraction exactly 2/3 at the free-space range edge, real detects 44% beyond it, a two-ray twin with height error δh disagrees ≈
4h_rδh/(λr)and is worse than free space at short range, a height-jitter ensemble scores Brier 0.119 vs 0.197 deterministic. Stylised. - A point-target radar twin of two unresolved scatterers: it has the right median, so what does it get wrong, and does averaging looks converge where it says?Point-target radar twin of two unresolved scatterers under ideal monopulse: real mean is exactly the strong scatterer and median exactly the power centroid, outside-span probability
arccos(r)/π, a variance-matched Gaussian twin is 27× too optimistic at a 3σ gate (r=0.9), averaging looks floors at bias2r²/(1+r²)where the twin predicts√(var/N), and the median beats the mean for r≥0.477. Stylised. - A constant-variance Gaussian camera twin of Poisson photon counting: which dark/bright decision rule does it teach, and what does that cost on the real sensor?Constant-variance Gaussian camera twin of Poisson photon counting: the real Bayes threshold is the logarithmic mean, the twin's the arithmetic mean (7.28 vs 8.00 for 4 vs 12), a detector tuned in it has 1.25–1.83× the optimal error and 23× at λ0=200 (λ1=2λ0), and a square-root twin recovers the optimum in 8 of 9 pairs. Stylised.
- A radar twin whose targets occupy a single range cell: how far around a strong target does the real matched filter ghost, and does tapering fix it?Single-cell radar twin vs a real matched filter: exact Rician ghost false alarms (0.020 at 20 dB, 1.0 at 30 dB for rect vs the twin's 1e-6), ghost zone radius growing
√10per 10 dB, taper gain exactly sidelobe difference + ENBW loss, and a 60 dB Hamming zone 6× Hann's despite the lower peak sidelobe. Stylised. - A link twin with independent packet loss says to send repeats back to back: what does burstiness do to repetition coding for shared maps, and what does spacing buy?Independent-loss link twin vs a bursty loss chain for repeated map updates: exact residual
p·q_g^(r−1), the twin's 5 back-to-back copies leave 81–311× the claimed loss at λ=0.5–0.8, spacing needs 6–36 slots for two copies, and with ≤8 copies the best design is 12–154 slots of latency vs the twin's 4. - A lidar twin without atmospheric loss overstates range in fog: by how much, how sensitive is it to a mis-set extinction, and what does it do to a driving policy?Clear-air lidar twin vs fog: detection range
W(αr0)/αoverstated by exactlye^{αr}, range error isW/(1+W)<1times the extinction error, a policy sized on median fog is violated 50% of the time (5%-quantile range: 5%, 43.5% slower), and one extinction calibrated on a bright target fails for dark ones in patchy fog. Stylised.
All 164 Digital twins & sim-to-real projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.