How well does Freivalds' check work in floating point?
research/freivalds-float
Freivalds' matrix-product check in floating point: rank-one corruption missed with probability exactly erf(t/(√2F)) (worst case for fixed norm), erf^m for m probes, Rademacher probes stuck at ½ for any size, measured float32 noise floor, and 1/erf grinding tries when the probe is hashed from the result.
What it found
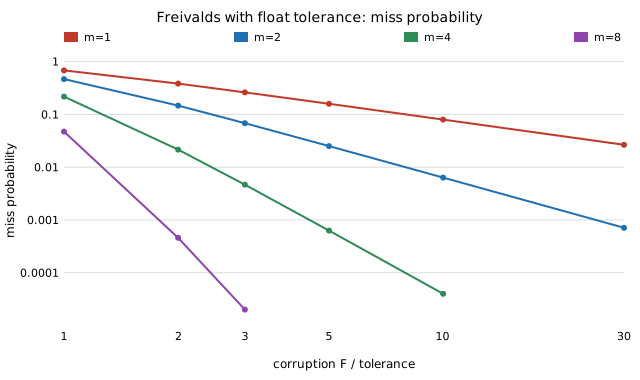
Checking a claimed matrix product by A(Br) ≈ Cr needs a tolerance t, so the error bound becomes size-dependent: a rank-one corruption of Frobenius norm F is missed by a Gaussian probe with probability exactly erf(t/(√2F)), rank one is the worst case for fixed F, and m probes give erfm (4 probes for 1% at 3t). Rademacher probes miss a two-entry corruption with probability ½ at every size. Emulated float32 noise grows ≈n0.9; a hashed probe with free retries lets a cheater grind in 1/erf tries (125 at 100t). Stylised, additive corruption.
A figure from its own output
Paper, code and results
More in Detection & tolerances
- How many skipped training steps hide in the loss noise?Detecting skipped training steps from the loss alone: hidden compute is the loss curve inverted at the noise band (
f* = 1−(1+(e^q−1)/r)^{−1/β}), grows as reducible loss falls, seed noise sets a floor no eval size removes, simulation matches within 1.5 points, and the loss test is worth ≈4.4 step audits at best. - How much can a provider steal by serving a cheaper model?Detecting a provider that serves a cheaper model on a fraction of queries: mixture e-process (valid under peeking), delay
∝ 1/(f p² χ²), so the cheater's best response is to leak rarely and steal∝ √NnotN; closed-form audit rate and cost-optimal check rate(hK/2Nc)^{2/3}. - Can you slash while watching the data stream?Anytime-valid slashing of miscalibrated verifiers: peeking z-test falsely slashes 37% of honest verifiers (nominal 5%), an e-process holds ≤α by Ville, detection delay ≈
ln(1/α)/KL(within 12%), q-free mixture costs ×1.36. - Can two verifiers be compared while the data streams in?Anytime-valid duels between two verifiers: the optimal betting e-process on the Brier difference grows at exactly
KL(q‖(rA+rB)/2), a peeking z-test falsely declares a winner 19–38% of the time at nominal 5%, a bet mixture stays ≤3.8% and costs 15–41% more decisions. - Which of n verifiers is best, decided at any time?Anytime-valid best-of-n verifier identification: delay set by the rival whose report midpoint sits nearest
q(the best opposite-side rival, not the runner-up), mixture within 1.35–1.60× of oracle, elimination 4–5× cheaper, peeking declares a false best in 59% of ties vs 1.6%. - How much can Byzantine verifiers move an aggregate?Byzantine-robust aggregation of verifier reports: mean bias
βBunbounded, median biasσΦ⁻¹(1/(2(1−β)))independent of B, trimmed-mean closed form for τ≥β verified by simulation.
All 14 Detection & tolerances projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.