Can two verifiers be compared while the data streams in?
research/forecast-duel
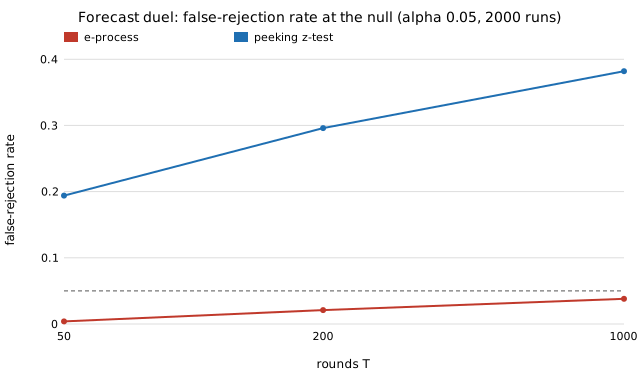
Anytime-valid duels between two verifiers: the optimal betting e-process on the Brier difference grows at exactly KL(q‖(rA+rB)/2), a peeking z-test falsely declares a winner 19–38% of the time at nominal 5%, a bet mixture stays ≤3.8% and costs 15–41% more decisions.
What it found
For fixed reports rA, rB and binary outcomes with frequency q, the Brier difference is a two-point gamble and A is better exactly when q is on A’s side of the midpoint π=(rA+rB)/2. Betting a fraction λ of wealth on it gives an anytime-valid e-process whose best bet grows at exactly KL(q‖π), so the expected decision time is ln(1/α)/KL. A z-test checked after every task falsely declares a winner in 19–38% of null runs at nominal 5%; a uniform mixture over bets stays at or below 3.8% and costs 15–41% extra tasks; a bet twice too large has negative growth. Fixed reports, i.i.d. outcomes. Stylised.
A figure from its own output
Paper, code and results
More in Detection & tolerances
- Which of n verifiers is best, decided at any time?Anytime-valid best-of-n verifier identification: delay set by the rival whose report midpoint sits nearest
q(the best opposite-side rival, not the runner-up), mixture within 1.35–1.60× of oracle, elimination 4–5× cheaper, peeking declares a false best in 59% of ties vs 1.6%. - How much can Byzantine verifiers move an aggregate?Byzantine-robust aggregation of verifier reports: mean bias
βBunbounded, median biasσΦ⁻¹(1/(2(1−β)))independent of B, trimmed-mean closed form for τ≥β verified by simulation. - Can a verifier tell from old-task losses that a continual-learning job skipped or shortchanged tasks?Auditing skipped or partial continual-learning training from old-task losses: exact loss law (
ρ^{t−1}[(1−2m₁+m₂)(r/d)λᵏ+(r/d)ρ(ρᵏ−λᵏ)]), a skipped task is ≥d/(d−r)× worse but only clearly so inside a lag window, detecting a skipper takes ~0.7/s²jobs at any lag, a 10% step shortfall needs ~9600. - Is an interference-free or mean-noise-rise radar twin right when robots' radars interfere with each other?Interference-free or mean-noise-rise radar twin vs intermittent mutual radar interference between robots: exact closed-form per-frame Pd, real Pd plateaus at 0.656 (no-hit probability), mean-rise twin 9% optimistic at Pd ≥ 0.9 yet badly pessimistic for hit-tolerant missions, geometry knowledge helps 9-of-10 missions (Brier 0.089 vs 0.101). Stylised.
- Does demand-driven simulation mislead leak detection on a stressed water network, and where does pressure-driven demand change the answer?Net3 leak signals under demand-driven and pressure-driven demand (WNTR): identical at 1 to 1.25 times base demand and nearly so at 1.5 times; beyond that both models fail because the pumps cannot meet demand (simulated; one network).
- How small a water-main leak can pressure sensors find, and does a changepoint detector beat a threshold or CUSUM?Water-leak detection from pressure residuals on EPANET's Net3 (WNTR): at a 5% weekly false-alarm budget, 5 sensors and 10% demand error, CUSUM finds all leaks the sensors can see at 4% of demand but 8% at 1% (3% of all leaks); demand error, not sensor noise or detector choice, sets the limit (simulated leaks; BattLeDIM L-Town was unreachable).
All 14 Detection & tolerances projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.