How many solver iterations does a physics twin need to hold a stack of boxes still?
research/free-pgsstack
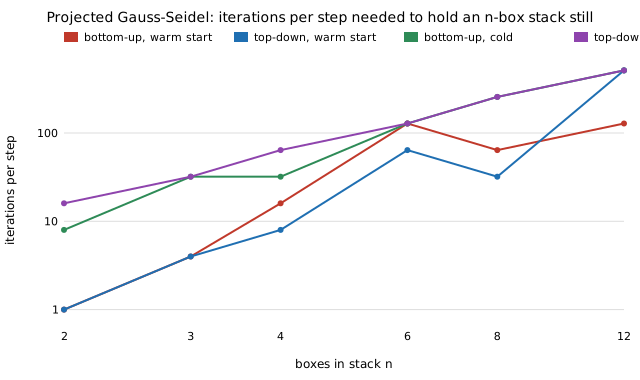
How many solver iterations does a physics twin need to hold a stack of boxes still? A projected Gauss-Seidel solver at 60 Hz needs 16 for 4 boxes, about 128 for 6 and over 2048 for 16 or more, and extra iterations do not reliably help.
What it found
A from-scratch projected Gauss-Seidel (sequential-impulse) contact solver at 60 Hz on a 1-D stack of n unit boxes starting at rest, checked against the exact static contact impulses. The iterations per step needed to hold the stack (speed under 1 mm/s, total overlap under 0.1 mm, and for every larger count tried) grow faster than n: 1 at n = 2, 8 to 16 at n = 4, 64 to 128 at n = 6, 128 to 512 at n = 12, and over 2048 for n = 16 (bottom-up warm start) or n = 32 (every variant). Sixteen iterations hold at most 4 boxes. More iterations do not reliably help: at n = 16, 1024 holds and 2048 does not. Cold start needs more at small n and is mixed at large n; sweep order has no clean rule. One-dimensional, normal force only, one step size and Baumgarte factor, no real engine run; the cause of the non-monotone behaviour is not isolated.
A figure from its own output
Paper, code and results
More in Digital twins & sim-to-real
- If the twin is optimistic, how often does a rollout test certify a policy that is not safe?Exact: a twin that fails 10% less often than reality lifts the chance of certifying a 5%-failure policy from 0.049 to 0.087 (fixed test, 1% vs 5%), 20% less often to 0.147, and guarding against a 1.5x optimism costs 2.2 times the rollouts
- Can a rollout cap on a sequential certification test be set without losing the 5% error guarantee, and what does it cost?Follow-up to free-sprtcap: re-tuning a capped SPRT's boundaries and final cut so both errors stay at or below 5% exactly costs, for 1% vs 5% (fixed test 181 rollouts), a mean of 107 rollouts at a cap equal to the fixed size and 90 at twice it, against 90 to 95 for the plain capped test that overshoots the error; the fixed test needs 181.
- What is the cheapest capped certification test in the worst case, not just at the two design rates, and what does it cost at the ends?Follow-up to free-sprtopt: an exact linear programme gives the capped certification test with the smallest worst-case mean over failure rates between p1 and p0; for 1% vs 5% at a cap of 362 it needs 123.8 rollouts at worst against 131.0 for the average-optimal test and 181 for the fixed test, at the price of 3 to 6% more rollouts at the two design rates.
- How few rollouts can a capped certification test need while keeping both errors at 5%, and how far is the tuned SPRT from that optimum?Follow-up to free-sprtcut: backward induction gives the optimal capped test, 98.9 rollouts on average for 1% vs 5% at a cap of 181 (proved within 0.2% by a dual bound), against 107.3 for the grid-tuned SPRT and 181 for the fixed test; the tuned SPRT is 3 to 9% above the optimum at every cap tried.
- Is the overflow twin's lead over black-box models on a real two-tank rig statistically real? A 0.13 V RMSE gap over ARX 4/4 with a block-bootstrap 95% interval of 0.06 to 0.20 VIs the overflow twin's lead over black-box models on a real two-tank rig statistically real? A 0.13 V RMSE gap over ARX 4/4 with a block-bootstrap 95% interval of 0.06 to 0.20 V; the iid bootstrap is about three times too narrow. Test-trace sampling only, not fit variance.
- Does the overflow twin's lead over ARX survive refitting on a real two-tank rig? A 0.13 V gap in 100% of refits with 87.5% of the training data, but 0.07 V and 84 to 90% of refits with 50 to 75%Does the overflow twin's lead over ARX survive refitting on a real two-tank rig? A 0.13 V gap in 100% of refits with 87.5% of the training data, but 0.07 V and 84 to 90% of refits with 50 to 75%. Overlapping windows, fixed optimiser start.
All 164 Digital twins & sim-to-real projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.