How much does speech-recognition error hurt an always-on assistant's trigger policies at equal annoyance?
research/ambient-asrnoise
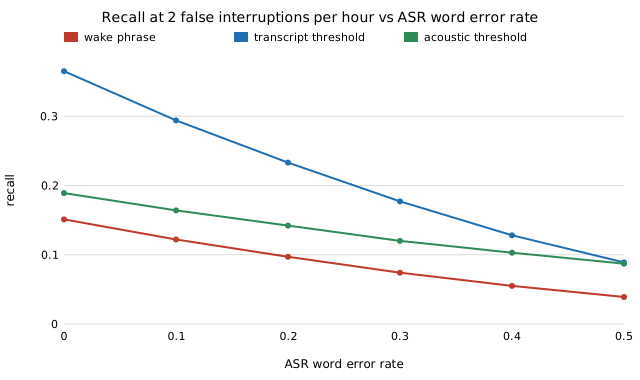
How much speech-recognition error hurts an always-on assistant's trigger policies at equal annoyance: from word error rate 0 to 0.5 a two-word wake phrase loses 74% of its recall and a transcript-reading threshold 76%, an acoustic-only score about 54%, and the transcript policy falls behind the acoustic one at WER 0.3 to 0.4 if its separation shrinks as (1-WER)^2 (stylised).
What it found
The ambient-interject world with an ASR word error rate (WER) entering each signal by assumption: a two-word wake phrase needs both words right, a keyword one, a transcript-reading intent score loses separation as (1−WER)k, an acoustic score is unaffected. At 2 false interruptions per hour, going from WER 0 to 0.5 cuts the wake phrase's recall from 0.151 to 0.039 (−74%) and the transcript threshold's from 0.365 to 0.089 (−76%), while the acoustic threshold falls from 0.189 to 0.087. With k = 1 the transcript policy stays marginally ahead at WER 0.5; with k = 2 the acoustic policy overtakes it at WER 0.25–0.4. Thresholds tuned at WER 0 stay under the false-interruption budget when deployed at higher WER. Stylised: the WER-to-signal mapping is assumed, not fitted to real recognition, and ASR confidence is not modelled.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- When moments of need cluster in time, does a cooldown, a boost or a back-off help an always-on assistant at equal annoyance?When moments of need cluster in time, does a cooldown, boost or back-off help an always-on assistant at equal annoyance: an episode-aware boost gains up to 0.05 recall under strong clustering, a cooldown always loses recall, back-off is a wash; stylised simulation.
- Under a storage limit, which transcripts should an on-device assistant keep, and what survives?What an on-device assistant should keep from a week of simulated transcripts: BM25 retrieval, extractive summaries and byte-limited retention policies (stylised)
- Which parts of an always-on Android listening service can be tested without a phone?Testable Kotlin core of an always-on listening service (re-framing, energy VAD, utterance segmenter, headset-drop policy; 7 tests pass under a shim) plus an unbuilt Android foreground-service sketch; no SDK, no device numbers
- When is a glance better than speech for an always-on assistant?When a glanceable display beats speech for an always-on assistant: a stylised utility model over noise, company, free eyes and message length, with sensitivity and twin-gap checks
- Does urgency, and a chime-plus-glance mode, change how an always-on assistant should deliver a message?Urgency classes and a chime-plus-glance mode added to the glance-vs-speech utility model for an always-on assistant: a stylised model with sensitivity and twin-gap checks
- How much reply latency can an always-on assistant hide by starting its pipeline before the speaker has finished?How much reply latency starting the ASR/LLM/TTS chain during the end-of-speech hangover hides, from the measured
ambient-pipelinestage times and an assumed within-turn pause model (hold-until-endpoint vs eager; extra runs per turn)
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.