How much reply latency can an always-on assistant hide by starting its pipeline before the speaker has finished?
research/ambient-speculate
How much reply latency starting the ASR/LLM/TTS chain during the end-of-speech hangover hides, from the measured ambient-pipeline stage times and an assumed within-turn pause model (hold-until-endpoint vs eager; extra runs per turn)
What it found
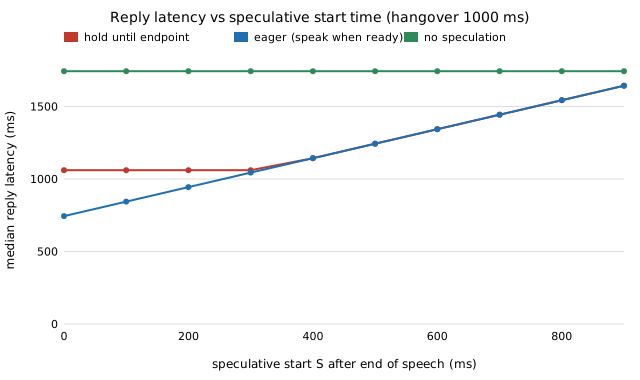
Using the measured ASR, LLM and TTS times from ambient-pipeline (a 682 ms median chain on one server CPU, six synthetic utterances), the reply pipeline starts after S ms of silence instead of after the full end-of-speech hangover H and the reply is held until H confirms the turn is over. Holding saves exactly min(chain, H − S): at H = 1000 ms the median reply falls from 1744 to 1061 ms, at the price of 0.7 to 1.9 extra pipeline runs per turn depending on S, and the just-in-time start S = H − chain is the cheapest that hides everything. Pause durations inside a turn are assumed (five lognormal settings, not data); with median 400 ms pauses no hangover up to 1.2 s keeps cut-offs under 10%. Closed forms agree with a Monte Carlo check.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- Can a sentence-completeness cue let an always-on assistant stop waiting so long before it replies?Can a sentence-completeness cue let an always-on assistant stop waiting so long before it replies: a stylised two-hangover endpointer cuts the mean wait from 913 to 574 ms at a 10% cut-off budget if no pause sits at a complete point, but only to 837 ms if half do; cue and pauses assumed.
- When is a second or third earbud tone worth it before a glance?How many repeated earbud tones before a glance are worth their annoyance, by urgency, tone gap and masking, in the
ambient-urgencyutility model (stylised) - How accurate must an always-on assistant's urgency label be before acting on it beats ignoring it?How accurate an urgency label must be before an always-on assistant should act on it: naive, Bayesian and label-ignoring policies in the
ambient-urgencyutility model (stylised) - How many audited messages does an always-on assistant need before it can trust a noisy urgency label?How many audited messages an assistant needs to estimate a noisy urgency label's confusion matrix and prior well enough to act on it: about 50 at moderate accuracy, with smoothing helping at tiny audit sets (stylised)
- What does a noisy auditor do to an assistant that learns its urgency label’s reliability from audits?What a noisy human auditor does to an assistant that learns its urgency label's reliability from audits: taking audit labels as truth biases the estimate and loses 8% to 69% of the label's gain at a 0.9 to 0.7 auditor, and correcting for a known auditor accuracy recovers it (stylised)
- How many gold-labelled audits replace noisy ones when the auditor’s accuracy is unknown?How many gold-labelled audits replace noisy ones when the auditor's accuracy is unknown: 25 gold audits match 1000 noisy ones read as truth, and a joint EM using 10 gold plus 200 noisy audits nearly reaches the true-parameter policy (stylised)
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.