How many gold-labelled audits replace noisy ones when the auditor’s accuracy is unknown?
research/ambient-goldaudit
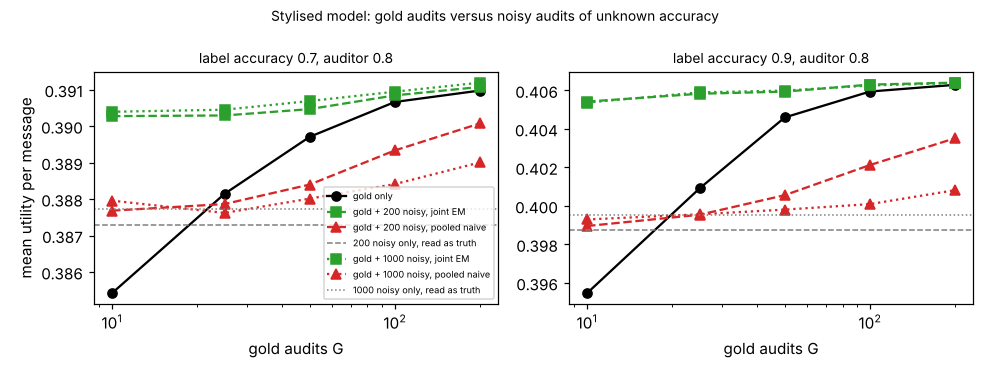
How many gold-labelled audits replace noisy ones when the auditor's accuracy is unknown: 25 gold audits match 1000 noisy ones read as truth, and a joint EM using 10 gold plus 200 noisy audits nearly reaches the true-parameter policy (stylised)
What it found
Extending the stylised noisy-audit model, 200 or 1000 audits from a 0.8-accuracy auditor read as truth give mean utility 0.387–0.388 (label accuracy 0.7) and do not improve with n, while 25 gold audits already match them and 10 do not. Pooling noisy with gold audits as truth is worse than gold alone. Fitting the mix, the label matrix and the auditor’s matrix jointly by EM, with 10 gold and 200 noisy audits, reaches 0.4054 against 0.4066 for the true parameters at label accuracy 0.9 (gold alone: 0.3955). The advantage vanishes by 200 gold audits. Stylised: uniform-error matrices, one auditor accuracy, EM started at the true value, round-number utilities.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- How should a fixed audit budget be split between gold-labelled and noisy audits?How to split a fixed audit budget between gold and noisy audits when gold costs 3 to 30 times more: all-noisy is worst or near-worst in all 12 cells, 25% on gold with a joint EM fit is within 0.0009 of the best, and all-gold loses when gold is expensive (stylised)
- Can an assistant learn its urgency label’s reliability from two noisy auditors, and what does a wrongly assumed auditor accuracy cost?Can the assistant learn its urgency label's reliability from two noisy auditors with no accuracy known (Dawid-Skene), and what does a wrong assumed auditor accuracy cost: over-trusting the auditor loses 31% of a 0.9 label's gain, and Dawid-Skene reaches within 0.0005 of the oracle at n = 1000 (stylised)
- What does Dawid–Skene do when the two auditors share their errors?What does Dawid-Skene do when the two auditors share their errors: it over-trusts them (auditor accuracy read as 0.909 for a true 0.8 at half shared) and loses part of its edge over trusting one auditor, falling to equal it when the second auditor is a copy, never below it (stylised)
- What if the two auditors only share errors on hard messages, and can a hardness-aware EM fix Dawid–Skene?What if the auditors only share errors on hard messages: Dawid-Skene's cost is much smaller than with copying (policy utility 0.4060 vs 0.4066 at 30% hard messages), reaching the naive estimator only in an extreme cell, and a hardness-aware EM recovers the classifier but cannot identify the hard share (stylised)
- Does a third auditor identify the hard-message share, and does it help plain Dawid–Skene?Does a third auditor identify the hard-message share: yes at the population level (P(hard) 0.300 from informed starts), only loosely at n=1000 (sd 0.07), and in the extreme cell plain Dawid-Skene with three auditors falls below the naive estimator (0.3912 vs 0.3992) while the hardness-aware EM does not (stylised)
- Does a likelihood-ranked multi-start make the hardness-aware EM robust to a poor start?Does a likelihood-ranked multi-start make hardness-aware Dawid-Skene robust to a poor start: at the population level yes (P(hard) 0.300, vs 0.500 and a lower likelihood from a poor single start), at finite n it matches one informed start, and where hardness is absent the hard share is not identified (stylised)
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.