Does a third auditor identify the hard-message share, and does it help plain Dawid–Skene?
research/ambient-third
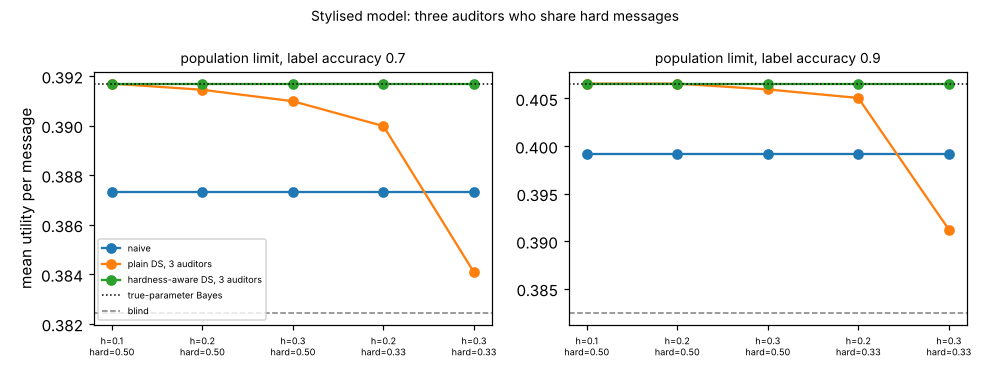
Does a third auditor identify the hard-message share: yes at the population level (P(hard) 0.300 from informed starts), only loosely at n=1000 (sd 0.07), and in the extreme cell plain Dawid-Skene with three auditors falls below the naive estimator (0.3912 vs 0.3992) while the hardness-aware EM does not (stylised)
What it found
Extending the hard-message model to three auditors (each 0.8 accurate overall, a fraction h of messages hard for all). A hardness-aware EM now recovers the hard share at the population level (P(hard) 0.300 from four informed starts, where two auditors left 0.24–0.35), but only loosely from samples (sd 0.07 at n = 1000) and a poor start still lands on a degenerate fit. Plain Dawid–Skene gets worse with more auditors: in the extreme cell (30% of messages at chance) it reads them as 0.85 accurate and its policy utility falls to 0.3912 at label accuracy 0.9, below the naive estimator’s 0.3992; the hardness-aware EM stays at the true-parameter 0.4066. Stylised: one shared-hardness model, uniform errors, round-number utilities; nothing measured on people.
A figure from its own output
Paper, code and results
More in Ambient AI assistant
- Does a likelihood-ranked multi-start make the hardness-aware EM robust to a poor start?Does a likelihood-ranked multi-start make hardness-aware Dawid-Skene robust to a poor start: at the population level yes (P(hard) 0.300, vs 0.500 and a lower likelihood from a poor single start), at finite n it matches one informed start, and where hardness is absent the hard share is not identified (stylised)
- How many starts does the likelihood-ranked multi-start need, and are grid starts better than random ones?How many starts does a likelihood-ranked multi-start need, and are grid starts better than random ones: one start is nearly enough with strong hardness or n = 1000, 4 starts reach the best optimum in most cells, more help only in the weak-hardness and null cells, and policy utility barely moves (stylised)
- Can a likelihood-ratio test tell “no hard messages” from “some”, and is the chi-square cutoff usable?Can a likelihood-ratio test tell no hard messages from some: chi-square cutoffs reject 35-72% of null data sets, a parametric bootstrap holds its level and detects h = 0.3 at n = 1000 but not h = 0.1 (stylised).
- Does the bootstrap likelihood-ratio test of “no hard messages” hold its level?Does the bootstrap likelihood-ratio test of no hard messages hold its level: 200 null draws per n give rejection 0.040-0.055 at nominal 0.05, all intervals containing 0.05 (stylised).
- Does the bootstrap test of “no hard messages” stay valid when the auditors differ in accuracy?Does the no-hard-messages bootstrap test keep its level when the three auditors differ in accuracy: 100 h = 0 draws per cell give rejection 0.00-0.10 at nominal 0.05, no inflation seen (stylised).
- Can an always-on assistant learn when to speak from accept/dismiss feedback alone, and what does it cost in dismissals?Can an always-on assistant learn when to speak from accept/dismiss feedback alone: greedy, epsilon-greedy and Thompson online policies vs an offline oracle, mostly negative (stylised)
All 46 Ambient AI assistant projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.