Can two independent passes agree on what a portfolio project is worth?
research/swe-value
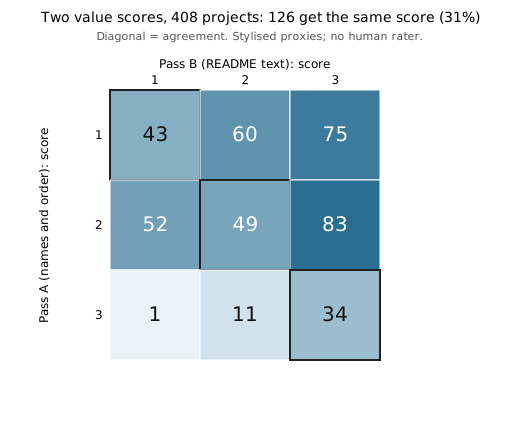
Can two passes agree on what a project is worth? A three-level value rubric scored two automated ways over 408 projects agrees at chance (kappa 0.07, 95% 0.01 to 0.13), partly from a name-family flaw fixed after the fact (0.25); a blind 30-project hand sample agrees better (0.45 to 0.57, wide intervals). Preliminary, track 10 milestone 3; no correctness term.
What it found
A three-level value rubric (follow-up, new question, listed milestone) scored over all 408 research/ projects by two automated passes, one from names and order and one from README text, plus a blind 30-project hand sample. The two automated passes agree at chance level (linear Cohen’s kappa 0.07, 95% bootstrap 0.01 to 0.13); a flaw in the name pass (108 *-twin projects counted as one follow-up chain) explains part, and fixing it after the fact lifts kappa to 0.25. Against the hand sample the text pass reaches 0.45 (0.24 to 0.65) and the fixed name pass 0.57 (0.24 to 0.81), n = 30, scored by the rubric’s author. Follow-ups add about as many lines as new projects (median 318 vs 328), so by the rubric they return less per line, a ratio that is largely built in. Preliminary and negative on the automated passes; no correctness term.
A figure from its own output
Paper, code and results
More in The software-engineering loop
- How many runs does a prompt experiment need, and is it safe to peek at it?When can a prompt experiment stop? Fixed-n, peek-every-pair and a mixture SPRT simulated on ledger-shaped outcomes: peeking declares an identical brief different in 21% (success rate) to 40% (value) of experiments, the mixture test stays under 5% but needs far more runs than a 97% success rate allows. Stylised, no candidate brief run; track 10 milestone 6, partial.
- Which track should the next run work on, and does a smarter pick beat a uniform one?Which track should the next run work on? Four allocation policies (uniform, greedy, bootstrap Thompson, knapsack-UCB) replayed offline on 7 tracks' scored projects: greedy and Thompson reach about 80% of the best-arm oracle against 60% for the current uniform pick, but value per line falls with order in 4 of 7 tracks, so the stationary replay overstates the gain. Stylised, offline only, no live trial; track 10 milestone 4, partial.
- How much of the track-allocation gain is luck of the project history?How much of the track-allocation gain is luck of the history? Block bootstrap of the sequential replay: at 20,000 lines greedy and Thompson beat uniform in 98–100% of 200 histories (intervals exclude zero), knapsack-UCB's does not; the small-budget loss does not reproduce. Stylised, offline only; follow-up to swe-decay.
- Do the gains from smarter track allocation survive when tracks run out of projects?Do track-allocation gains survive when tracks run out of projects? Sequential, no-replacement replay: at 20,000 lines greedy and Thompson keep most of their lead over uniform (pass A 134 and 130 against 114), but at 5,000 lines they lose to it (24 against 30). Stylised, offline only; track 10 follow-up to swe-allocate.
- Do the portfolio's committed results reproduce when the code is re-run?Do committed results reproduce? A seeded sample of 40 projects with a runnable experiment was re-run: 36 (90%, 95% Wilson 77% to 96%) matched their committed
results.txt, 3 timed out under load and 1 needed a missing voice model. Preliminary first pass of track 10, milestone 2; it checks reproduction only, not citations. Second sample of 60 (92 distinct projects pooled): 81 reproduced (88%), no finished run differed; re-running the 5 timeouts serially reproduced all, giving 86 of 92 (93%). - When research merges collide cleanly, is the result still right?When research merges collide cleanly, is the result still right? None of 92 clean replays was broken (28.7% of pairs within 60 min conflict); found and removed two duplicate README bullets the build missed.
All 43 The software-engineering loop projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.