A battery twin with no internal resistance: how much endurance and how large a burst does the real, sagging cell actually give?
research/sag-twin
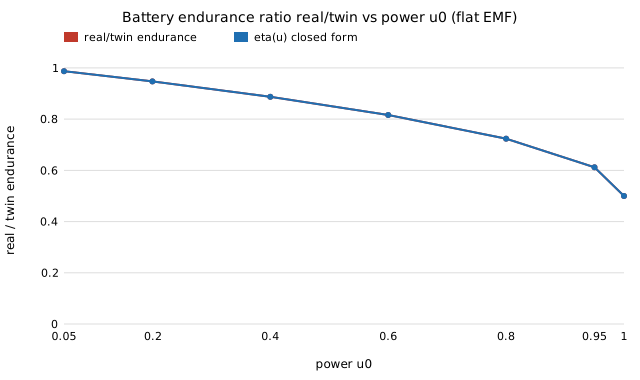
Battery twin with no internal resistance vs a real sagging cell: endurance exactly (1+√(1−u))/2 of the twin's (0.5 at the fold), 9–94% of charge stranded at the voltage cutoff, a burst of 0.5 fails below 51% charge where the twin's floor is 0 (a flat 20% reserve covers only a third of the full-charge limit), and a constant-derate refit errs +12% to +473% off its fit power. Stylised.
What it found
A UAV battery twin that keeps the open-circuit voltage curve but drops the series resistance overstates endurance by exactly 1/η(u) with η = (1 + √(1−u))/2 (up to 2× at the maximum-power fold, beyond which the real cell cannot deliver the power at all while the twin still quotes an endurance). With droop and a voltage cutoff, real/twin endurance is 0.86, 0.57, 0.30 at normalised power 0.2, 0.4, 0.6 and 9%, 37%, 66% of the charge is stranded. The deliverable burst power falls linearly with charge, so a burst of 0.5 fails below 51% charge where the twin's floor is zero, a flat 20% reserve covers only a third of the full-charge limit, and keeping a 0.6 burst deliverable leaves 35% of the twin's cruise time. A constant derate fitted at one power errs by +12% to +473% elsewhere, but the resistance is identified to 1–2% from tens of voltage–current samples, and a full-charge fit misses resistance that grows as the cell empties (endurance +42% to +85% too high). Stylised: simulated cell, linear curves, constant-power load, no polarisation or self-heating.
A figure from its own output
Paper, code and results
More in Digital twins & sim-to-real
- How many real trajectories does a classifier two-sample test need to reject a wrong digital twin, compared with a paired error test?How many real trajectories does a classifier two-sample test need to reject a wrong digital twin? Stylised pendulum: for a 20% Coulomb error a paired error test has power 0.98 at 100 trajectories vs 0.25 for the C2ST (which needs ~200), but for a 10% error the paired test stalls at 0.09–0.20 up to 800 while the C2ST reaches 1.00 at 400, and for same-variance noise-shape error the paired test has power ≤0.07 at every size. Null calibration approximate (60 replicates). Preliminary, simulated only.
- Was the paired digital-twin test weak, or was its statistic?Was the paired twin test weak, or was its statistic? Stylised pendulum, Student-t noise: the mean squared residual has power ~0.1 at a 10% Coulomb error up to n = 400, while median, trimmed, absolute and Huber statistics reach 0.94–1.00 from n = 50; Gaussian noise barely cares.
- Which robust paired test still catches a wrong digital twin when noise has infinite variance or whole runs go bad?Which robust paired test still catches a wrong digital twin when noise has infinite variance or whole runs go bad? Stylised pendulum, 10% Coulomb error: median and trimmed residuals reach power 1.00 under Student-t(2) cells but only 0.17–0.40 under bad runs, where a per-run median reaches 0.89–1.00; no statistic wins both.
- Which paired test of a digital twin survives both heavy-tailed cells and whole bad runs?Which paired test of a digital twin survives both heavy-tailed cells and whole bad runs? Stylised pendulum, 10% Coulomb error: a two-level statistic (trimmed mean of squared residuals within each run, then trimmed mean across runs) has power 0.99–1.00 at n = 50 under t(2) cells, bad runs at 0.86 and both at once, where the earlier single-level statistics each fail one case. Costs power under Gaussian noise (0.84 against 0.91).
- Which significance rule gives a classifier two-sample test the right false-rejection rate on a digital twin?Which significance rule gives a classifier two-sample test the right false-rejection rate on a digital twin? Stylised pendulum: cross-validated rules falsely reject 0.06 to 0.13 at a nominal 0.05, a holdout rank-sum test holds 0.04 to 0.06 at roughly twice the data cost. Preliminary, simulated only.
- Does a permutation test on the cross-validated statistic keep its size and beat the holdout rule's power on a digital twin?Does a permutation test on the cross-validated statistic keep its size and beat the holdout rule's power on a digital twin? Stylised pendulum: null rates 0.040 and 0.020, power 0.367 vs 0.183 for holdout at n=200 (Coulomb -10%).
All 164 Digital twins & sim-to-real projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.