How much of a human emotion codebook does a codebook induced from the text alone recover?
research/qual-induce
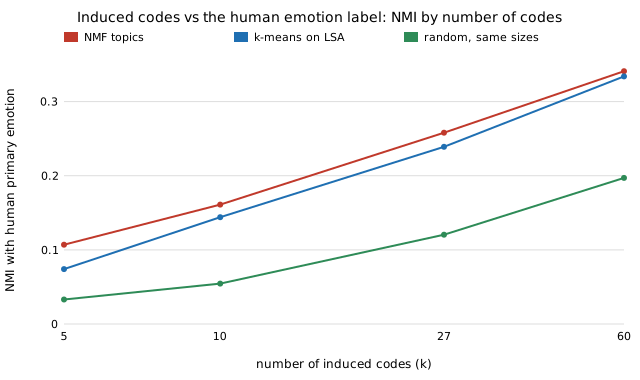
How much of a human emotion codebook does a codebook induced from the text alone recover? On 5,313 GoEmotions comments, NMF and k-means codebooks agree with the human emotion label above chance but weakly (NMI 0.26 vs 0.12 for 27 codes); the best single code per emotion reaches AUC about 0.6. Topic models, not an LLM.
What it found
On 5,313 real GoEmotions comments, codebooks induced from half the text with no labels (NMF topics and k-means on LSA, 5 to 60 codes) were applied to the other half and compared with the 27-emotion human codebook. Agreement with the human primary emotion was above a size-matched random assignment but small: NMI 0.26 for 27 NMF topics against 0.12 at chance, and 0.34 for 60 against 0.20. The best single induced code per emotion reached held-out AUC 0.60–0.62 on average, at least 0.7 for 14–25% of the 15 emotions with enough positives. NMF topics were almost uncorrelated (mean |r| 0.02); k-means with few codes was redundant (11% of pairs above 0.3 at k=10). The induced codes are topic models, not an LLM’s TopicGPT or LLooM codebook, and the agreement score rests on 1,906 comments with a unique majority emotion.
A figure from its own output
Paper, code and results
More in Machine learning on qualitative data
- Should you hand-code the items the coder called positive, or sample the audit by the coder's label?Should you hand-code only what the coder called positive, or sample the audit by the coder's label? On 3,188 GoEmotions comments, a positives-only audit had 0 of 1,000 intervals covering the truth for every coder (it misses the coder's false negatives); stratifying by label barely helped. Not an LLM; one corpus.
- Can you audit the coder's negatives at a lower rate and weight them back?Can you audit the coder's negatives at a lower rate and weight them back? On 3,188 GoEmotions comments, weighting removes the bias of a positives-only audit but the interval widens as the negative share falls (0.126 at 50%, 0.352 at 5%, 200 items) and under-covers below ~10%. Not an LLM; coders miss half the positives.
- With six groups, how many hand-coded items does it take for every group's prevalence to be right?With six groups, how many hand-coded items does it take for every group's prevalence to be right? On 3,188 GoEmotions comments, six 95% intervals covered all six truths in only 71 to 77% of 120 to 240-item equal audits (Bonferroni: 89 to 94%); a random audit could not estimate a 1.5% group at all. Not an LLM; one corpus.
- How many of the coder's negatives must you hand-code to recover the positives it missed?How many of the coder's negatives must you hand-code to recover the positives it missed? On 3,188 GoEmotions comments, about 50: coverage was 0.29 with 2, 0.87 with 10 and 0.94 with 50, whatever the audit's total size. Not an LLM; one corpus.
- Which confidence interval is right when only 5 to 20 of the coder's negatives are hand-coded?Which confidence interval is right when you hand-code only 5 to 20 of the coder's negatives? Not Wald: 0.63 coverage at 5 items against 0.94 for Wilson or Jeffreys on 3,188 GoEmotions comments. Not an LLM; one corpus.
- Does equal-numbers stratified auditing still match the optimal split when the coder errs more in the rare group?Does equal-numbers stratified auditing still match the optimal split when the coder errs more in the rare group? On 3,188 GoEmotions comments, injecting up to 30% extra label flips in the rarest 11% group moved the optimal audit share only from 0.53 to 0.56, and equal numbers stayed within 0.7% of optimal width. Not an LLM.
All 23 Machine learning on qualitative data projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.