Does a prompt-free human-vs-machine detector hold up on context families it never saw?
research/mimic-anycontext-detect
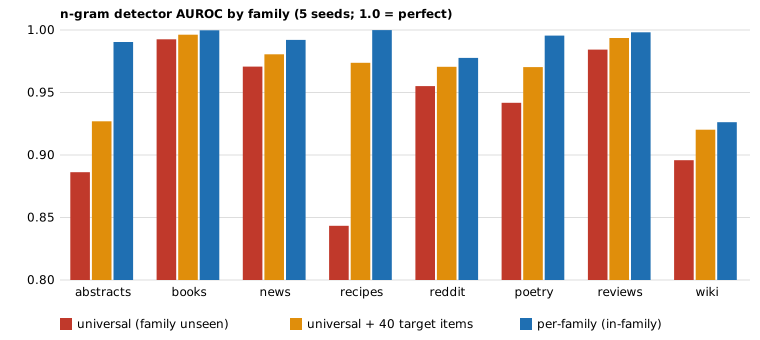
Does a prompt-free n-gram human-vs-machine detector hold up on context families it never saw? Detector side of mimic-anycontext with no LLM (model download was blocked): AUROC 0.934 on unseen families against 0.985 in-family, and 40 target items close most of the gap on recipes. Stylised: plain-prompt RAID text only.
What it found
Detector side of mimic-anycontext, run without an LLM because the model download was blocked. A TF-IDF n-gram logistic-regression detector is fitted on seven of eight RAID-derived families and scored on the eighth: mean AUROC 0.934 against 0.985 when fitted inside the family, worst on recipes (0.843), abstracts and wiki. Forty labelled target items close most of the gap on recipes. Held-out generators cost little (AUROC 0.90–1.00) and length does not explain it. Stylised: plain-prompt machine text only, one detector type; the prompt-optimising imitator is not tested.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- Which features let a human-vs-machine text detector carry over to a context family it never saw: words, characters, function words, formatting or length?Which features let a human-vs-machine detector carry over to a context family it never saw? Leave-one-family-out AUROC with train-only vectorisers: words 0.931, characters 0.916, both 0.938, function words alone 0.797, surface formatting 0.687 (below chance on abstracts and recipes), length alone 0.155 to 0.885 depending on family. Stylised: one classifier, plain-prompt RAID text, no LLM.
- Can a prompt make a 0.5B model detect machine text, and does the prompt carry to families it never saw?Can a prompt make a 0.5B model detect machine text, and does it carry to unseen families? Negative: the prompted Qwen2.5-0.5B detector is inverted (mean AUROC 0.278 plain, 0.293 universal on held-out families, none above 0.5 on any family) while the n-gram detector gets 0.93. Stylised: one small model, 16 prompts, plain-prompt RAID text.
- Does MAUVE, a distribution-level score, rank human-vs-machine gaps the way a text detector does?Does MAUVE rank human-vs-machine gaps the way a text detector does? Across 20 RAID family × model cells MAUVE (lexical embedding) and a cross-fit n-gram detector agree loosely (Spearman −0.60) and disagree on recipes and news; every cell is far below the human-vs-human null (0.92 to 0.99). Preliminary, no GPT-2 features.
- Can an imitator fool a prompt-free human-vs-machine text detector with cheap surface edits, such as typos, contractions or dropping the chat preamble?Can cheap surface edits (typos, contractions, no chat preamble) fool the n-gram human-vs-machine detector? Most move held-out AUROC under 0.005; 2% typos cost 0.012 and keeping half the text 0.051 (from 0.927), and a refit detector wins it back.
- How many words must an imitator change to evade a word n-gram human-vs-machine detector that it can read?How many words must an imitator change to evade a word n-gram human-vs-machine detector it can read? Deleting the 20 most machine-ward word types per text takes held-out AUROC from 0.948 to chance (0.487); a refit detector recovers to 0.94-1.00.
- How many detector queries does an imitator need to evade a human-vs-machine text detector it cannot read?How many detector queries does an imitator need to evade a word n-gram human-vs-machine detector it cannot read? About 100 score queries per text, deleting the 20 best word types, take held-out AUROC from 0.948 to 0.520 (white-box 0.487); blind deletion does nothing. Stylised, no fluency check.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.