Does MAUVE, a distribution-level score, rank human-vs-machine gaps the way a text detector does?
research/mimic-mauve
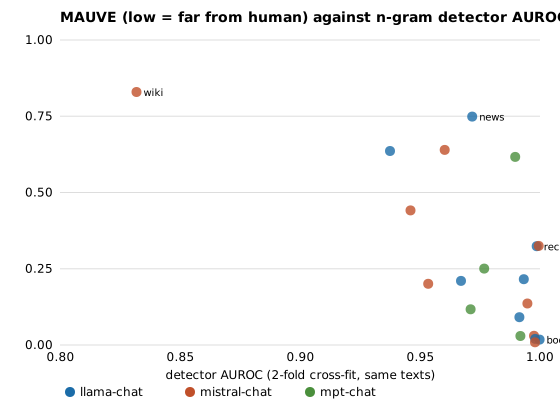
Does MAUVE rank human-vs-machine gaps the way a text detector does? Across 20 RAID family × model cells MAUVE (lexical embedding) and a cross-fit n-gram detector agree loosely (Spearman −0.60) and disagree on recipes and news; every cell is far below the human-vs-human null (0.92 to 0.99). Preliminary, no GPT-2 features.
What it found
MAUVE between human and RAID chat-model text in 20 family × model cells (TF-IDF/SVD embedding, 5 draws of 48–100 texts), against a cross-fit n-gram detector on the same texts. Human-vs-human MAUVE is 0.92–0.99; every human-vs-model cell is at most 0.83. MAUVE and AUROC rank cells loosely alike (Spearman −0.60, p = 0.005; wiki/mistral-chat is hardest for both), but disagree on recipes (AUROC 0.999, MAUVE 0.32) and news (0.97, 0.75), and MAUVE does not track the distinct-2 ratio (ρ = 0.24, n.s.). Preliminary: the embedding is lexical, not MAUVE’s usual GPT-2 features, so values are not comparable with the literature; plain-prompt text only, no LLM run.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- Can an imitator fool a prompt-free human-vs-machine text detector with cheap surface edits, such as typos, contractions or dropping the chat preamble?Can cheap surface edits (typos, contractions, no chat preamble) fool the n-gram human-vs-machine detector? Most move held-out AUROC under 0.005; 2% typos cost 0.012 and keeping half the text 0.051 (from 0.927), and a refit detector wins it back.
- How many words must an imitator change to evade a word n-gram human-vs-machine detector that it can read?How many words must an imitator change to evade a word n-gram human-vs-machine detector it can read? Deleting the 20 most machine-ward word types per text takes held-out AUROC from 0.948 to chance (0.487); a refit detector recovers to 0.94-1.00.
- How many detector queries does an imitator need to evade a human-vs-machine text detector it cannot read?How many detector queries does an imitator need to evade a word n-gram human-vs-machine detector it cannot read? About 100 score queries per text, deleting the 20 best word types, take held-out AUROC from 0.948 to 0.520 (white-box 0.487); blind deletion does nothing. Stylised, no fluency check.
- Does refitting a human-vs-machine text detector on attacked text stop a black-box evader?Does refitting a text detector on attacked text stop a black-box evader? It settles after one refit: fresh-attack AUROC stays near 0.81 (from 0.719) while clean AUROC falls from 0.948 to about 0.90. Stylised, no fluency check.
- Does a prompt-free human-vs-machine detector carry over to a generator or decoding it never saw?Does a prompt-free detector carry over to a generator or decoding it never saw? The
mimic-contextsn-gram detector loses 0.01 to 0.02 AUROC on a chat model left out of the fit (0.96 to 0.98 left out) and 0.025 to 0.05 on a left-out decoding (sampling 0.936); averaging over four same-source texts lifts AUROC to 0.999. Preliminary, plain-prompt RAID text only. - Does adding a zero-shot perplexity score to the n-gram detector help it catch machine text in families it never saw?Does adding a zero-shot perplexity score to the n-gram detector help on unseen families? The two scores are uncorrelated within class, but averaging them lifts held-out AUROC only from 0.926 to 0.935 (paired gain +0.009, interval −0.010 to +0.026); fitted stacks do no better. Preliminary, 720 held-out texts, small scorer, no LLM run.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.