If a human-vs-machine detector's threshold is set for a 5% false-positive rate, does that rate hold on a kind of text it never saw?
research/mimic-threshold
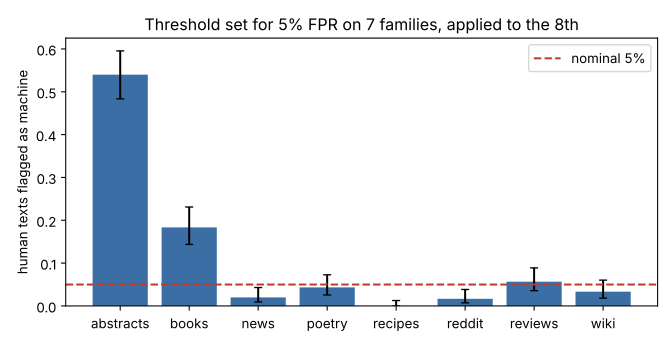
If a detector's threshold is set for a 5% false-positive rate, does it hold on an unseen text type? Leave-one-family-out with the mimic-contexts n-gram detector: realised rate 0.00 to 0.54 (abstracts 0.54, books 0.18), and recipes catch 1.7% of machine text. Preliminary, plain-prompt RAID text only.
What it found
The mimic-contexts n-gram detector is fit on seven RAID families and its threshold set so 5% of human text is flagged (out-of-fold), then applied to the eighth. Realised false-positive rates run from 0.00 to 0.54: abstracts 0.54, books 0.18, while news, poetry, recipes, reddit, reviews and wiki sit at 0.00–0.06. On recipes the cut-off is too strict instead: it catches 1.7% of machine text where a threshold set on recipes would catch 46%. AUROC does not show this (books has the best, 0.993, and the second-worst rate). Preliminary: plain-prompt RAID text, one detector type, one split, no LLM run.
A figure from its own output
Paper, code and results
More in Adversarial human imitation
- How many human texts does it take to re-set a detector's threshold for a 5% false-positive rate on a new kind of text?How many human texts does it take to re-set a detector's threshold for a 5% false-positive rate on a new kind of text? About 80: with the plain 95th percentile k = 20 gives a mean false-positive rate of 9% (36% chance above 10%), k = 80 gives 6.1%; a conformal rule holds 4.9% but costs recall and needs 19+ texts. Stylised, RAID text, one n-gram detector.
- How many texts from one source does a weak human-vs-machine text detector need before a batch verdict is reliable?How many texts from one source does a weak human-vs-machine detector need before a batch verdict is reliable? Four all-machine texts give AUROC 0.997 (one text: 0.935); a quarter-machine source needs about 32; but a threshold set on 150 human texts drifts from 7% to 15% false flags at k = 32. Preliminary, RAID text, one n-gram detector.
- Does a classifier two-sample test catch digital-twin errors that a paired trajectory error misses?Does a classifier two-sample test catch digital-twin errors that a paired trajectory error misses? Stylised pendulum: boosted-tree AUROC 0.72 for a friction error whose RMSE is a quarter of the sensor noise, 0.92 for Gaussian-vs-Student-t noise at zero paired error. Preliminary, simulated only.
- Does a kernel MMD test catch the same wrong digital twins as a classifier two-sample test?Does a kernel MMD test catch the same wrong digital twins as a classifier two-sample test? Stylised pendulum: raw-trajectory MMD is blind to a Coulomb-friction error (power 0.05 to 0.06) that boosted trees catch from n = 200, but MMD on second differences detects a +25% noise-level error at 0.97 from n = 100.
- Does a classifier two-sample test see the integrator, timestep and friction gaps of a MuJoCo digital twin?Does a classifier two-sample test see the integrator, timestep and friction gaps of a MuJoCo digital twin? Stylised pendulum: AUROC 0.98 for Euler at 0.02 s, 0.53 (null) for a paired error of 0.003 rad, 0.92 for Gaussian-vs-Student-t noise at zero paired error. Preliminary, simulated only.
- Does a kernel MMD test catch the same wrong MuJoCo digital twins as a classifier two-sample test?Does a kernel MMD test catch the same wrong MuJoCo digital twins as a classifier two-sample test? Stylised MuJoCo pendulum: boosted-tree C2ST power 1.00 at n = 200 for Euler at 0.02 s and a noise-shape error where MMD stays near 0.05; MMD on second differences catches a +25% noise-level error; friction errors undetected by all at n <= 200.
All 41 Adversarial human imitation projects →
Other research topics
Proper scoring & elicitation28Effort & peer prediction9Verification games & slashing19Detection & tolerances14Markets as routers13Prediction-market design9Paying contributors8Decentralised training systems23Digital twins & sim-to-real164LLM chip design loops40Robot manufacturing loops53Ambient AI assistant46Self-replicating manufacturing34Simulation-first design64Engineered clothing45Task-specific AI accelerators40Algorithmic chip-design loops42Open-source purpose-built robots44The software-engineering loop43Adversarial human imitation41Open-source residential construction41Autonomous multi-angle capture34Sensing, imaging and 3D31Energy supply and dense energy storage39Robot societies among people31Agentic co-design of low-cost robots27Laundry-hanging robots25Machine learning on qualitative data23Robots on the building site27Civilizations & group psychology1History & human sciences1
Produced with AI assistance (Claude). Results are from the code in this repository and are simulated or stylised unless the abstract says otherwise; nothing here implies affiliation with or endorsement by any lab, researcher or company cited. MIT licensed.